4 min read
The scarce resource picks the model
I choose Sol, Terra or Luna by whether I am short of time, tokens, or the right to be wrong.
GPT-5.6 is three models and a reasoning dial. I do not treat the fifteen settings as a menu. I ask what I am short of. A person waiting. Tokens and quota. Or the right to be wrong.
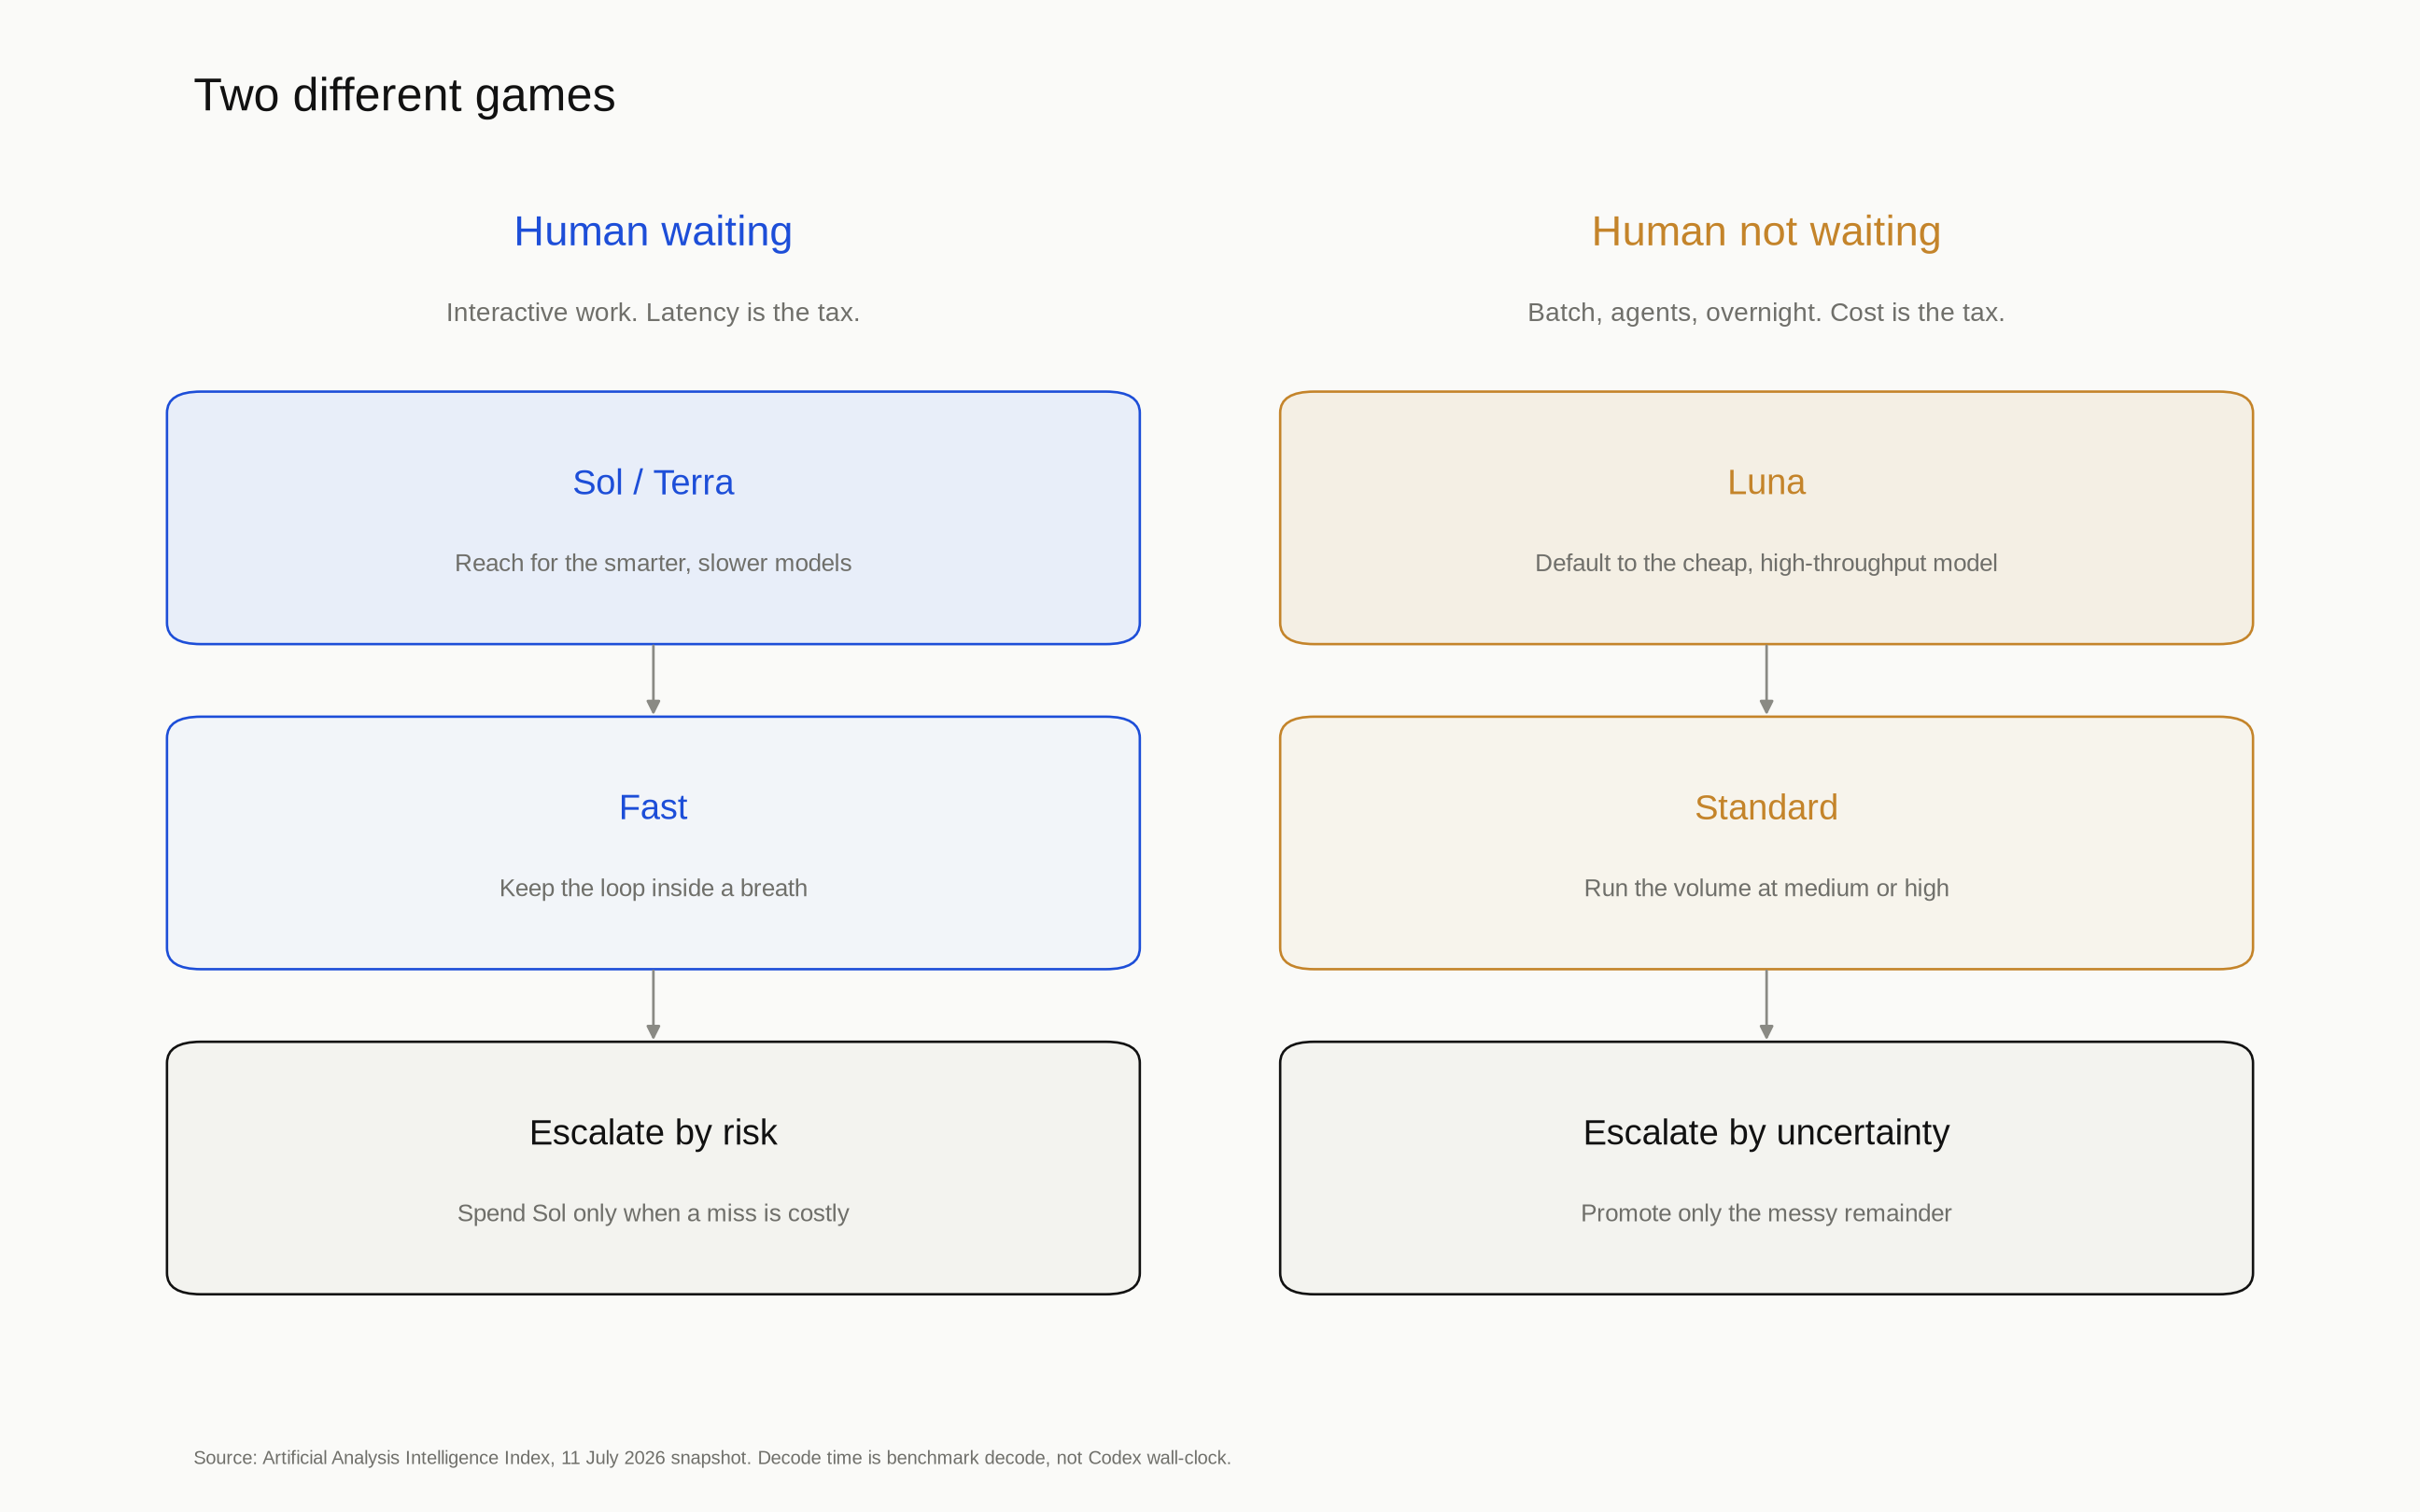
If someone is sitting in the editor, I pay for time. If the job can run overnight, I pay for tokens. If a miss is expensive, I spend Sol on the judgement and Luna on the typing.
I do not default to Terra because it sits in the middle.
Two games
In the editor, a cheaper model that makes me wait is not cheap. Overnight, Sol prices on test rewrites are just a habit.
What they cost
Sol is the flagship. Terra is the middle. Luna is the volume model. gpt-5.6 is Sol.
All three take a 1.05M context window and 128K max output. Current list prices:
| Model | Input / 1M | Cached | Output / 1M |
|---|---|---|---|
| Luna | $0.20 | $0.02 | $1.20 |
| Terra | $2.00 | $0.20 | $12.00 |
| Sol | $4.00 | $0.40 | $20.00 |
Sol at $4 / $20 is a promo through at least 21 November 2026. In July, Luna was $1 / $6 and Sol was $5 / $30.
What the board actually shows
The charts use Artificial Analysis from 11 July 2026. Decode time is their benchmark, not Cursor. The cost column is launch-era. Luna is cheaper on tokens now. I am not using this as a verdict on your repo.
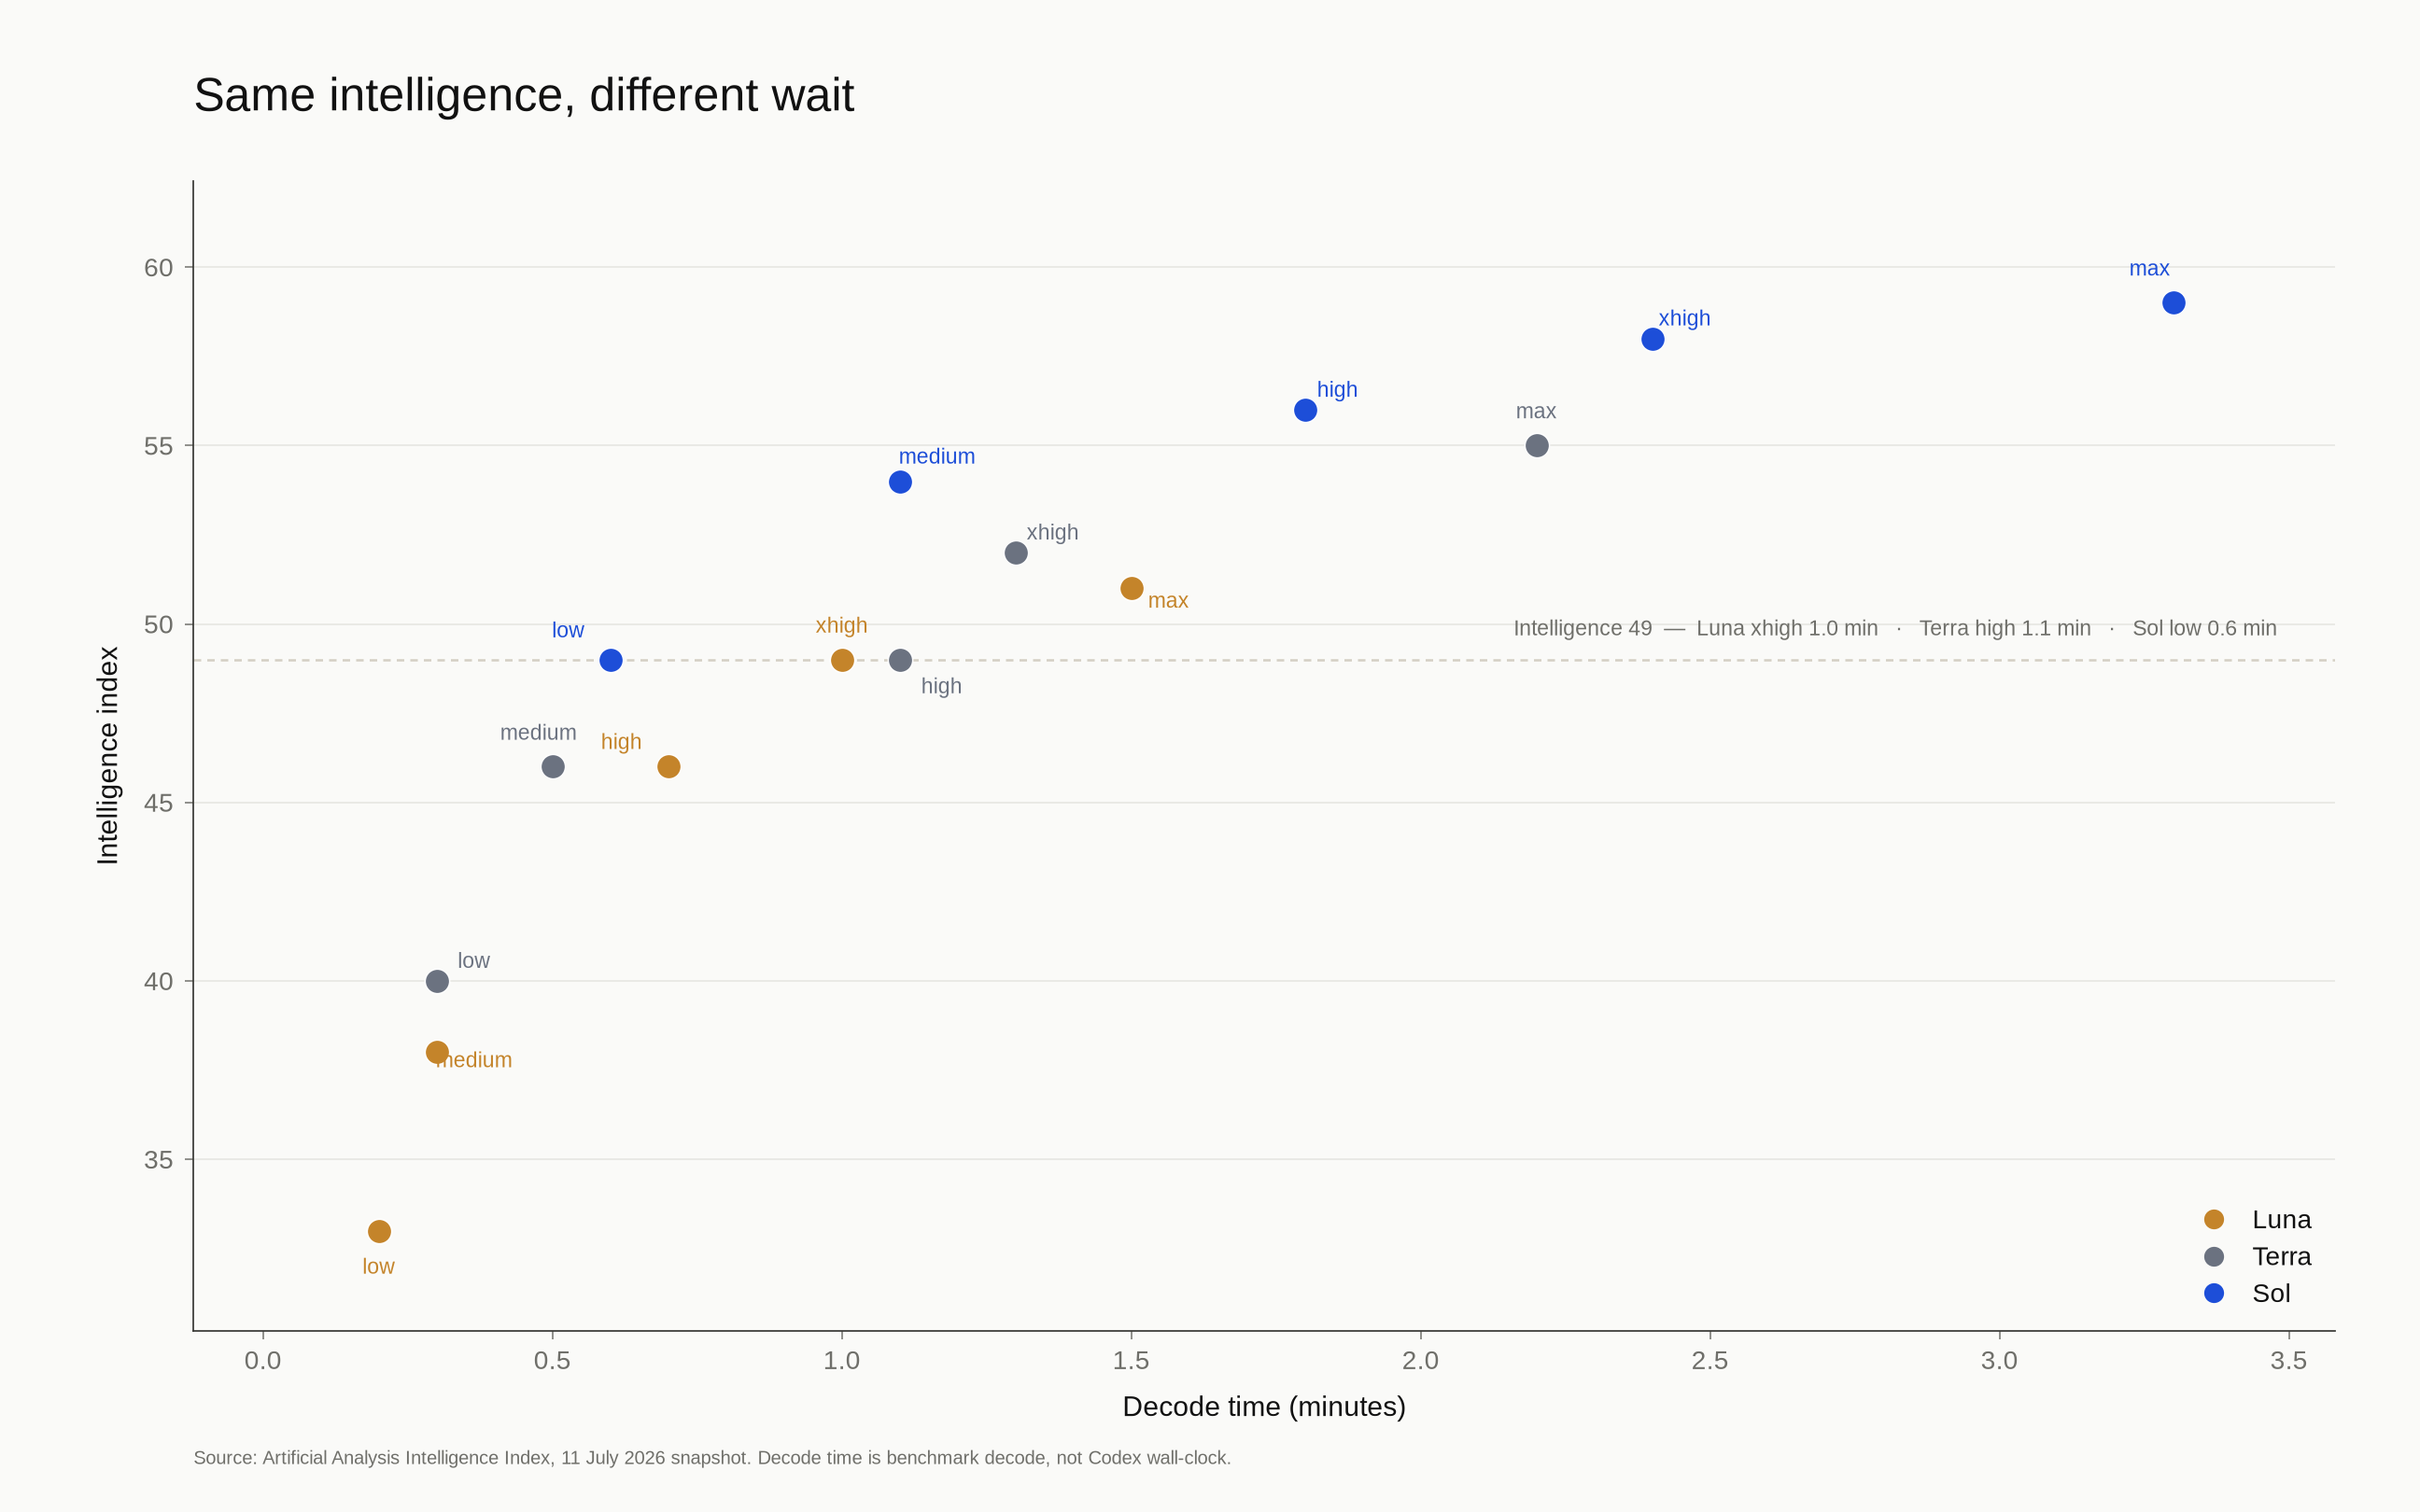
Sol is not always the slow one. It is slow when I keep turning the effort dial.
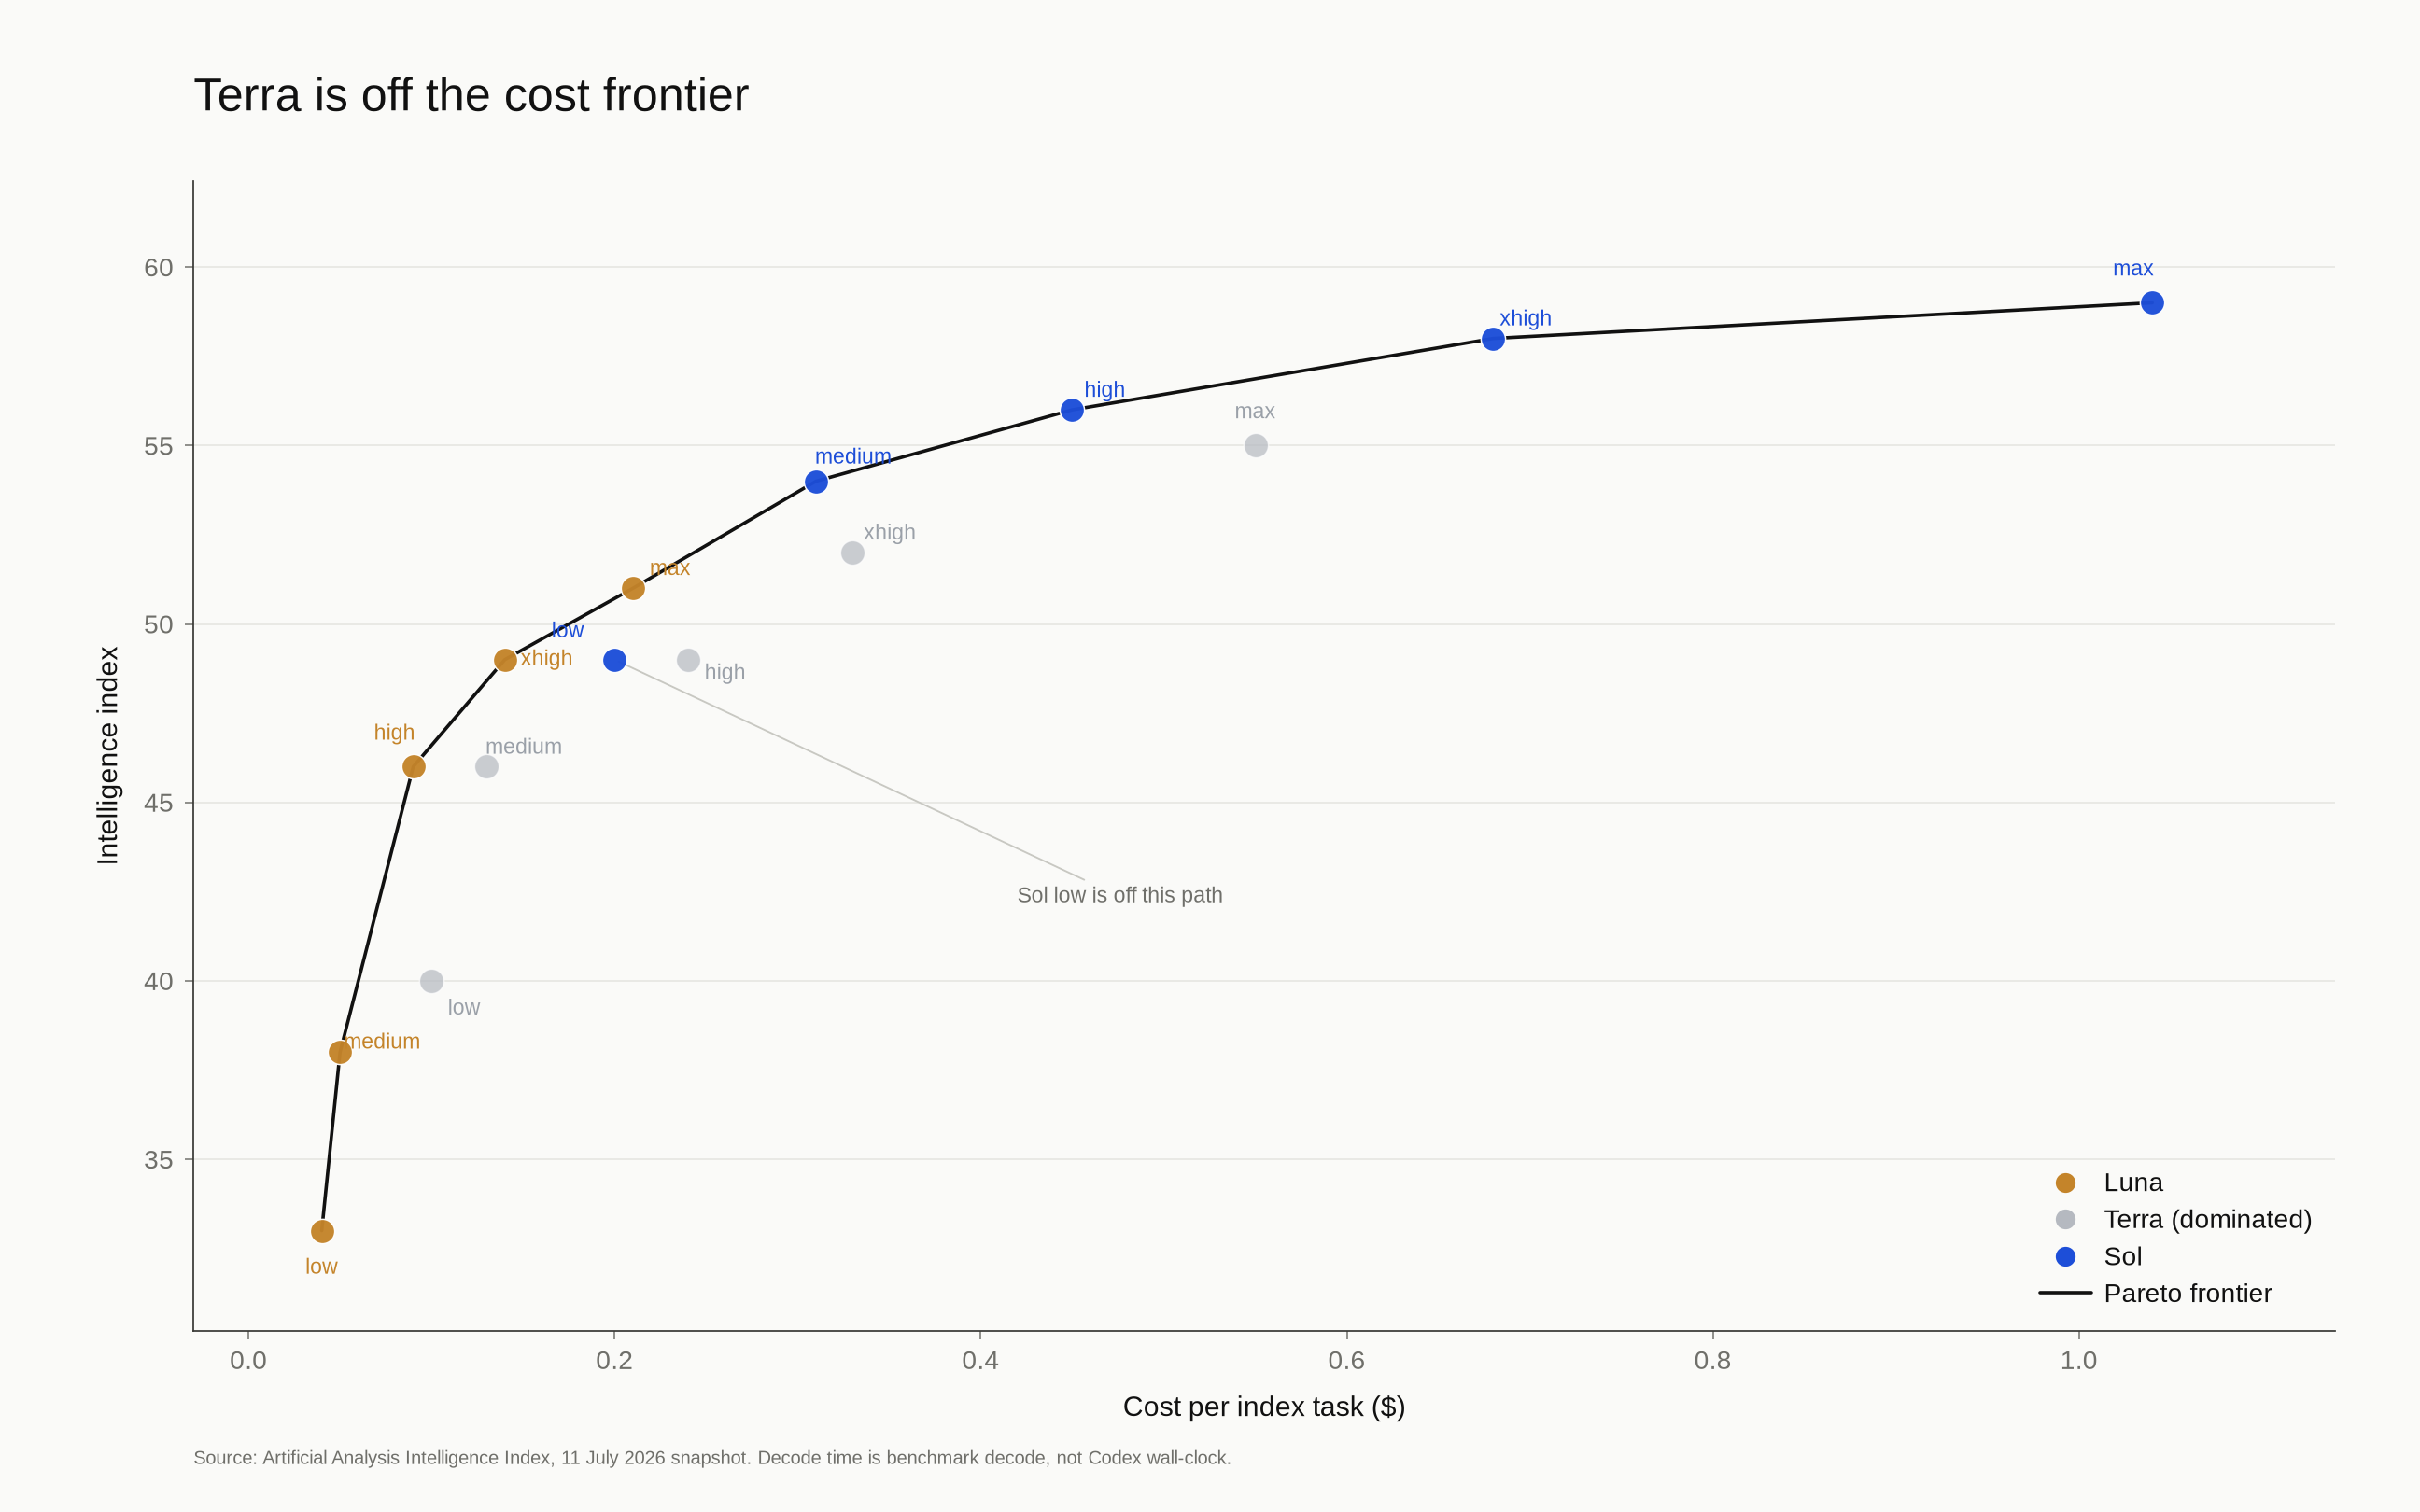
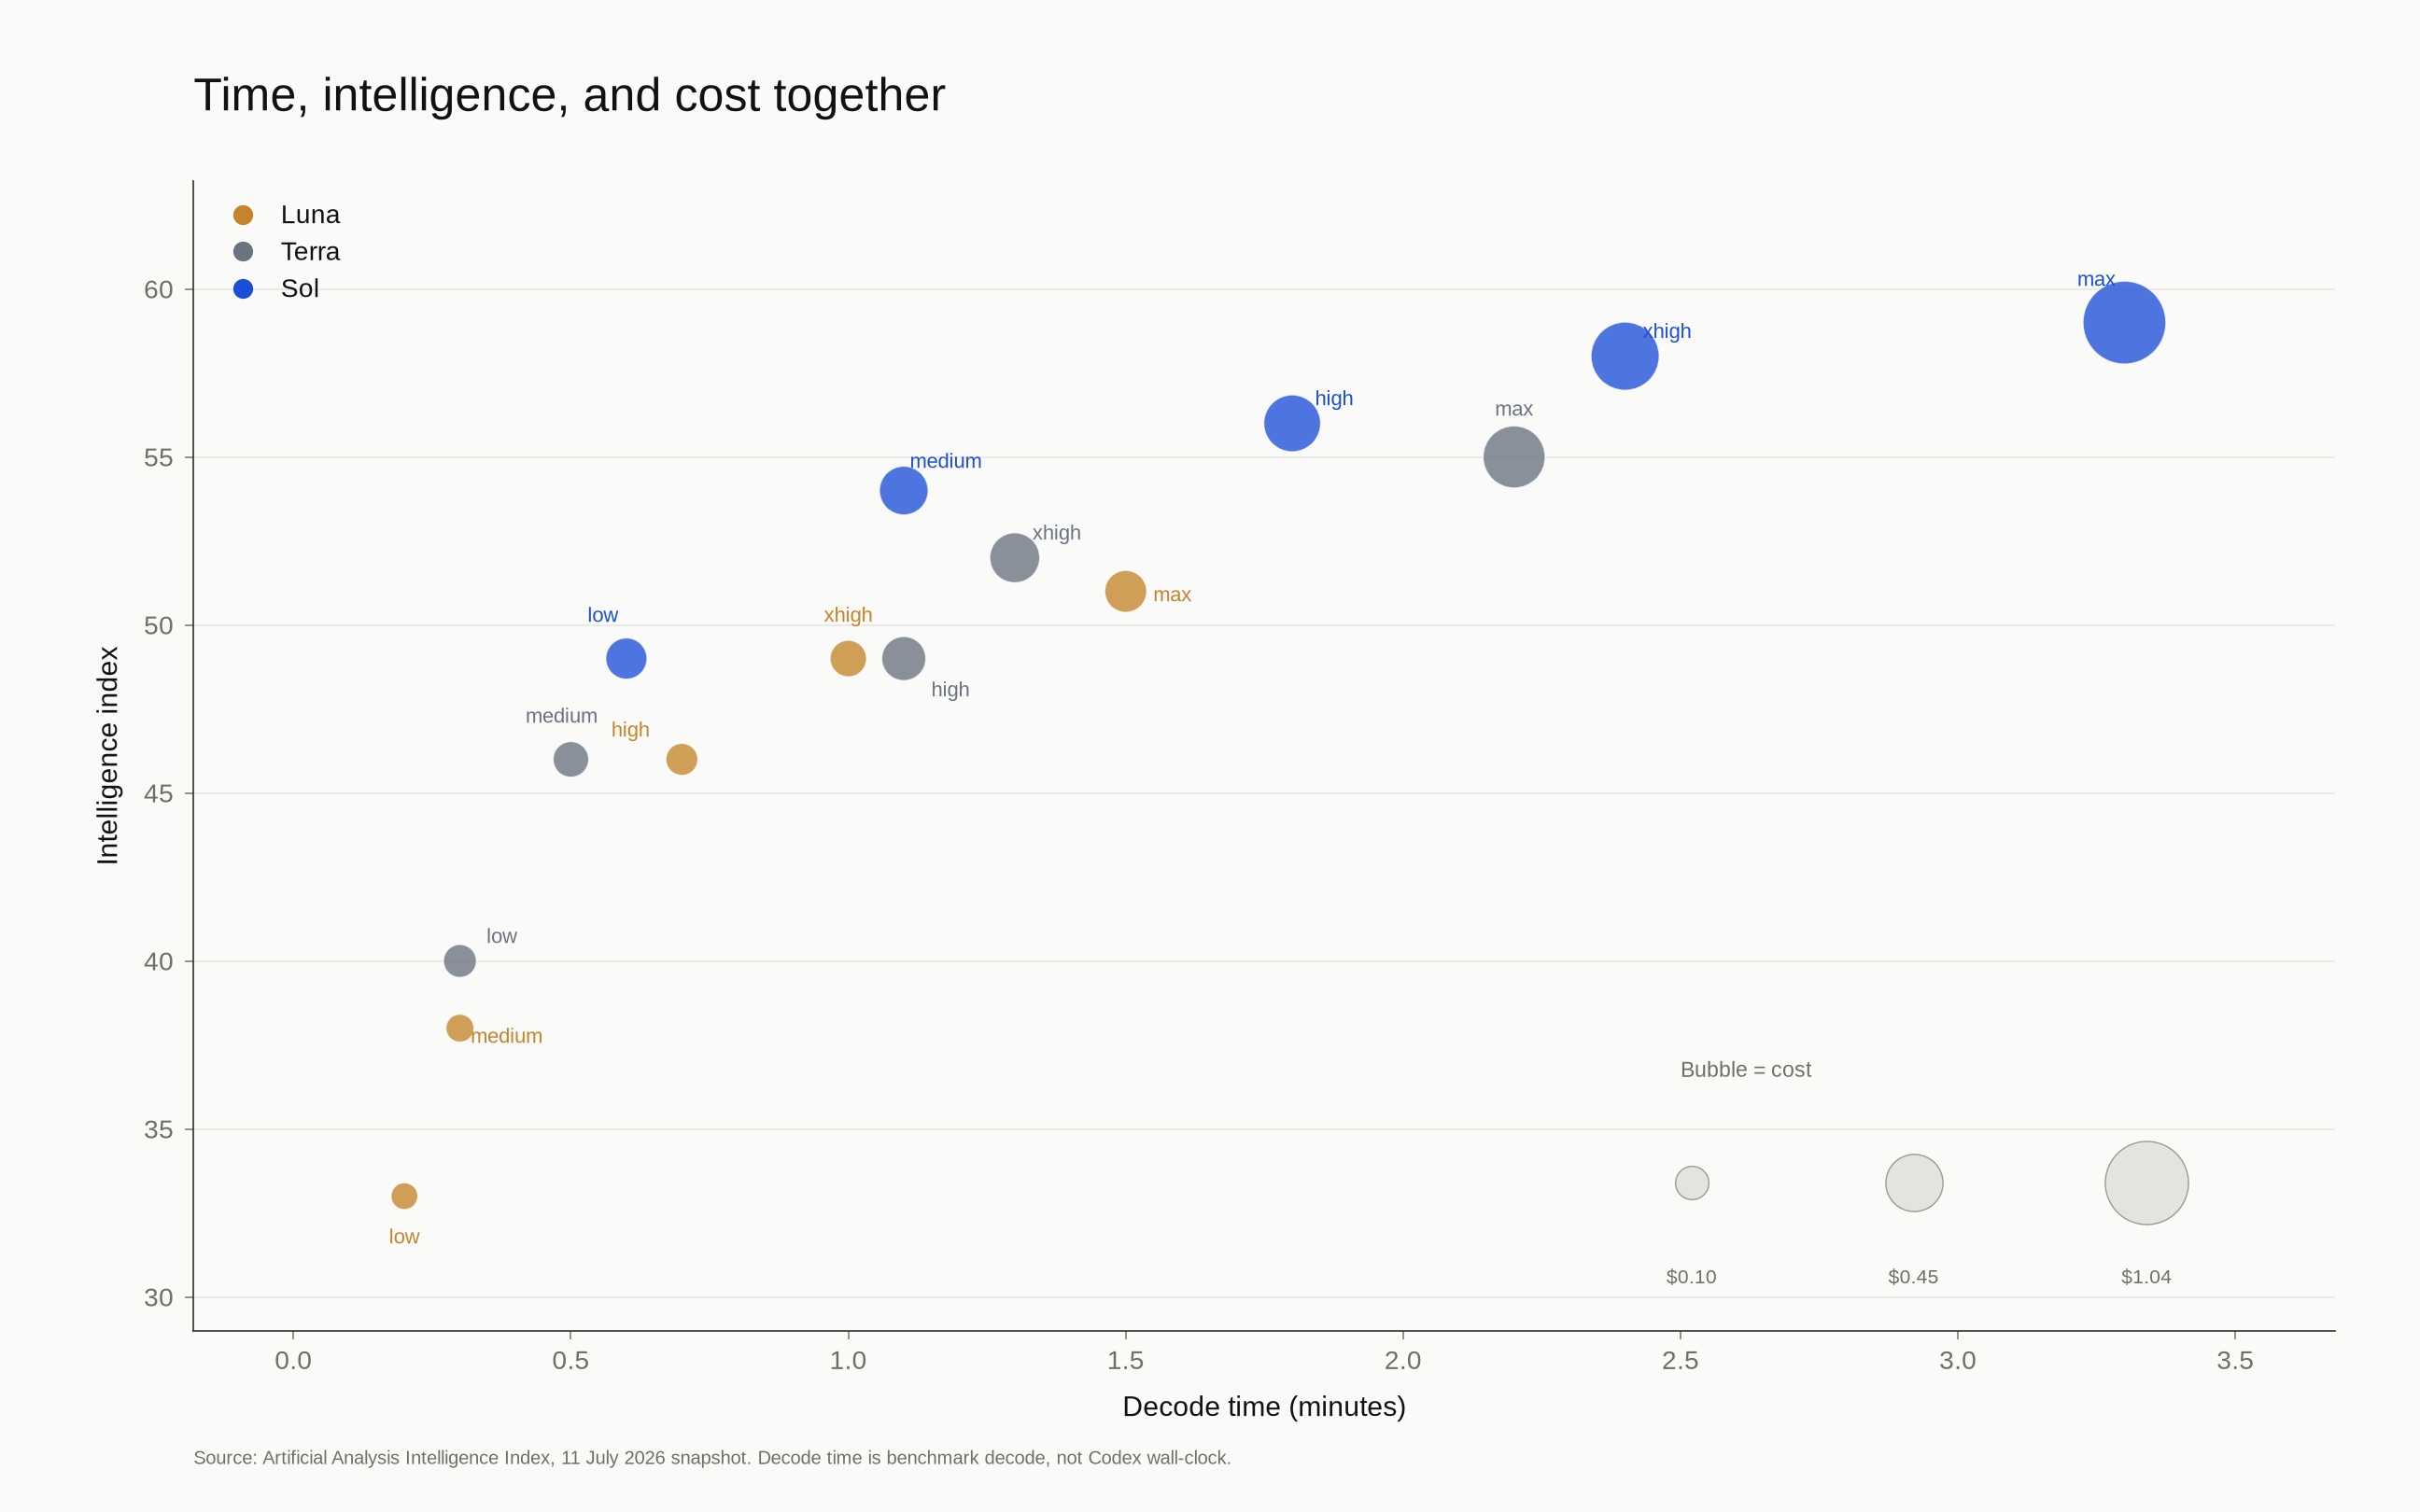
If Terra wins, it should win on my repo. Not because the name sounds like a compromise.
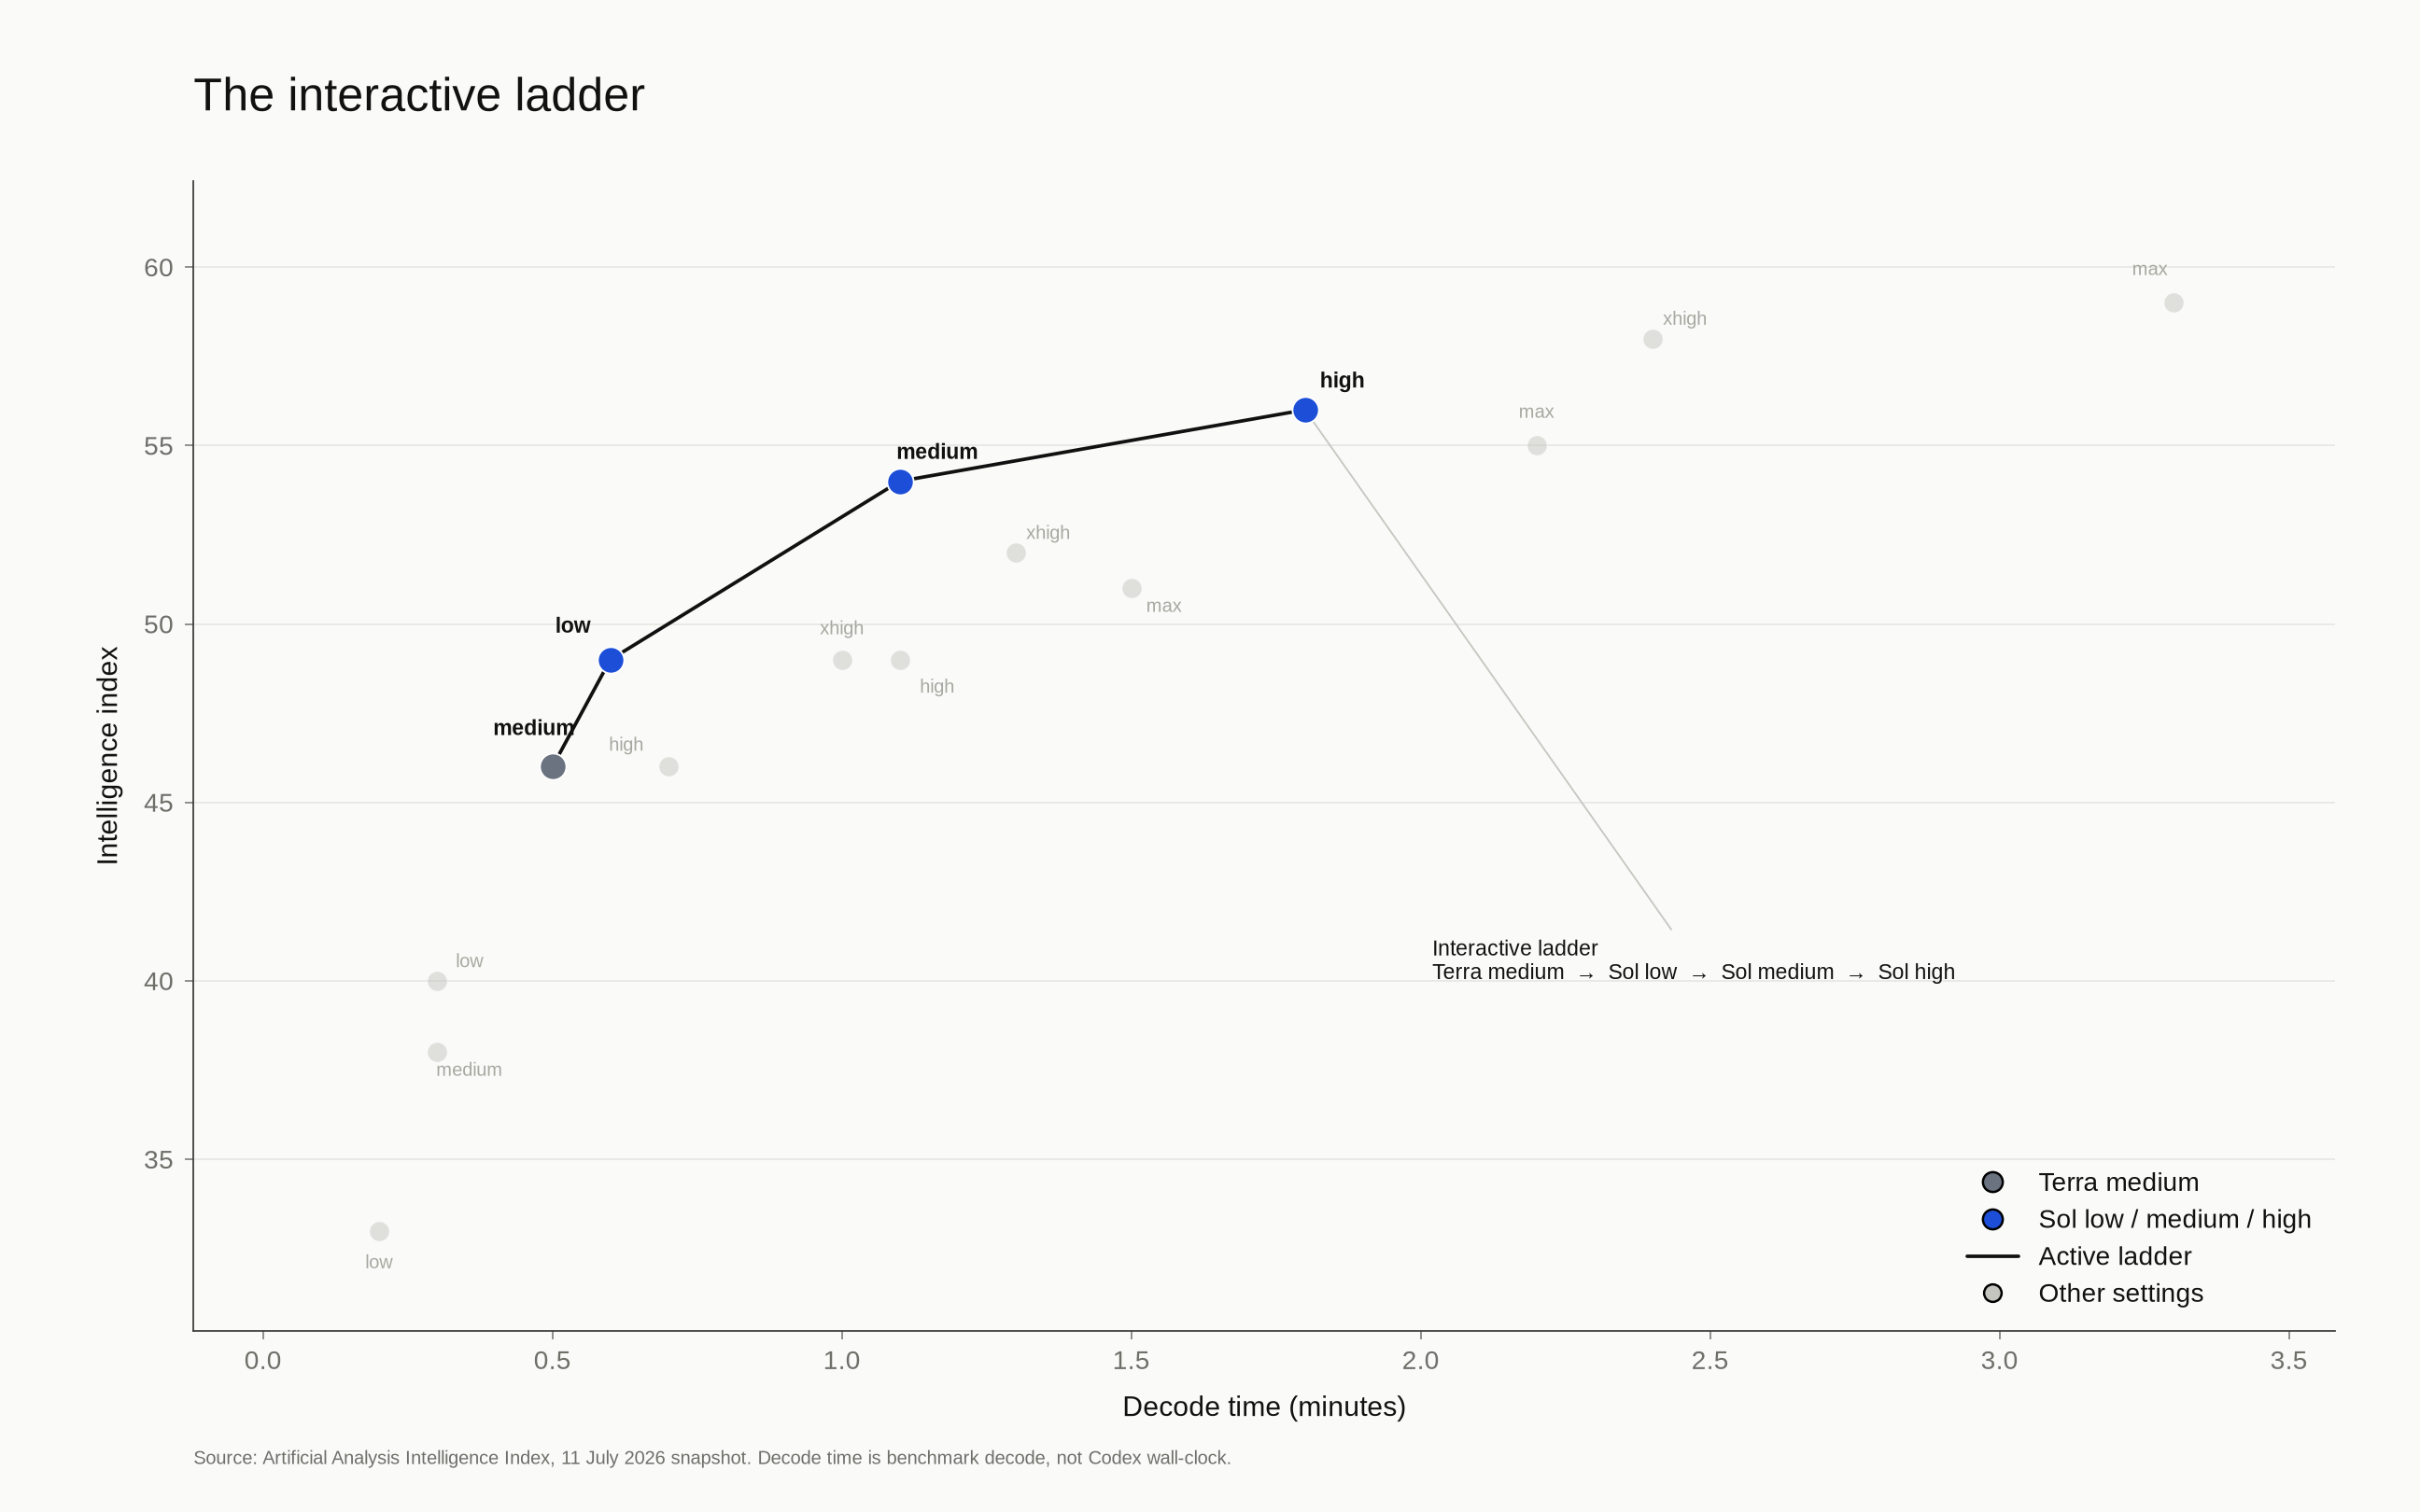
Effort
The dial is none, low, medium, high, xhigh and max. I start at medium. I use low when I need the answer now. I use max when I already know medium failed.
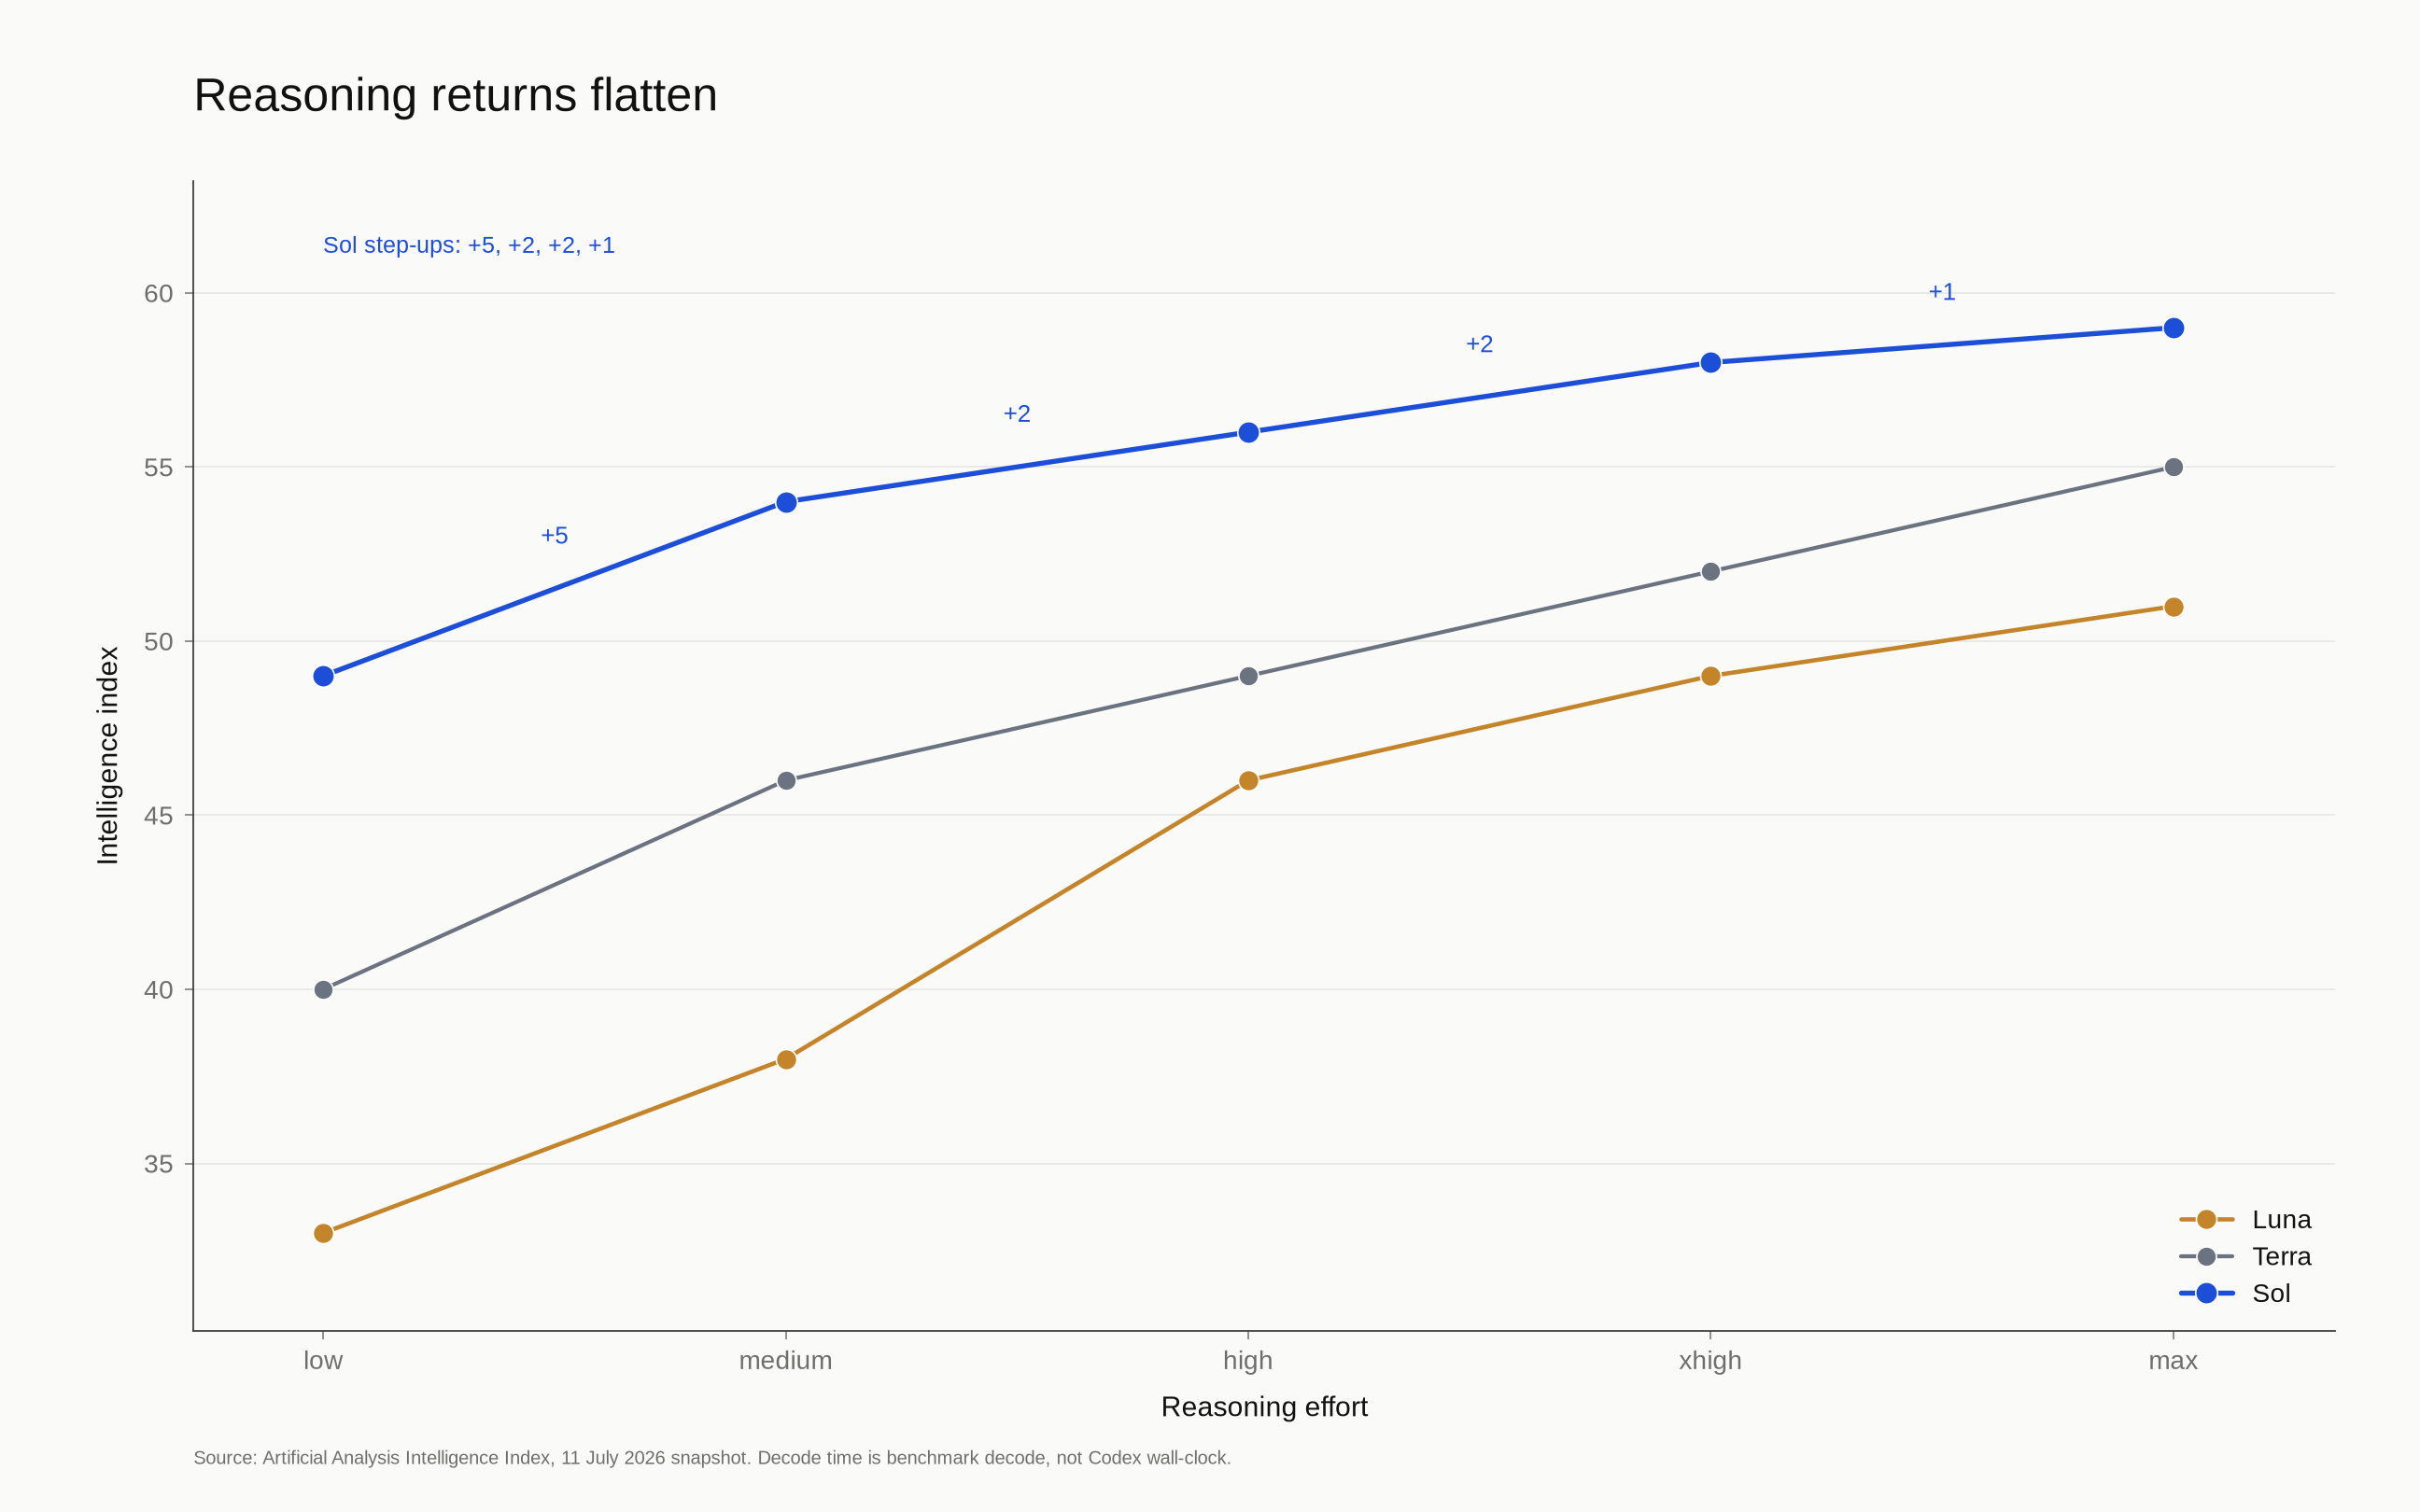
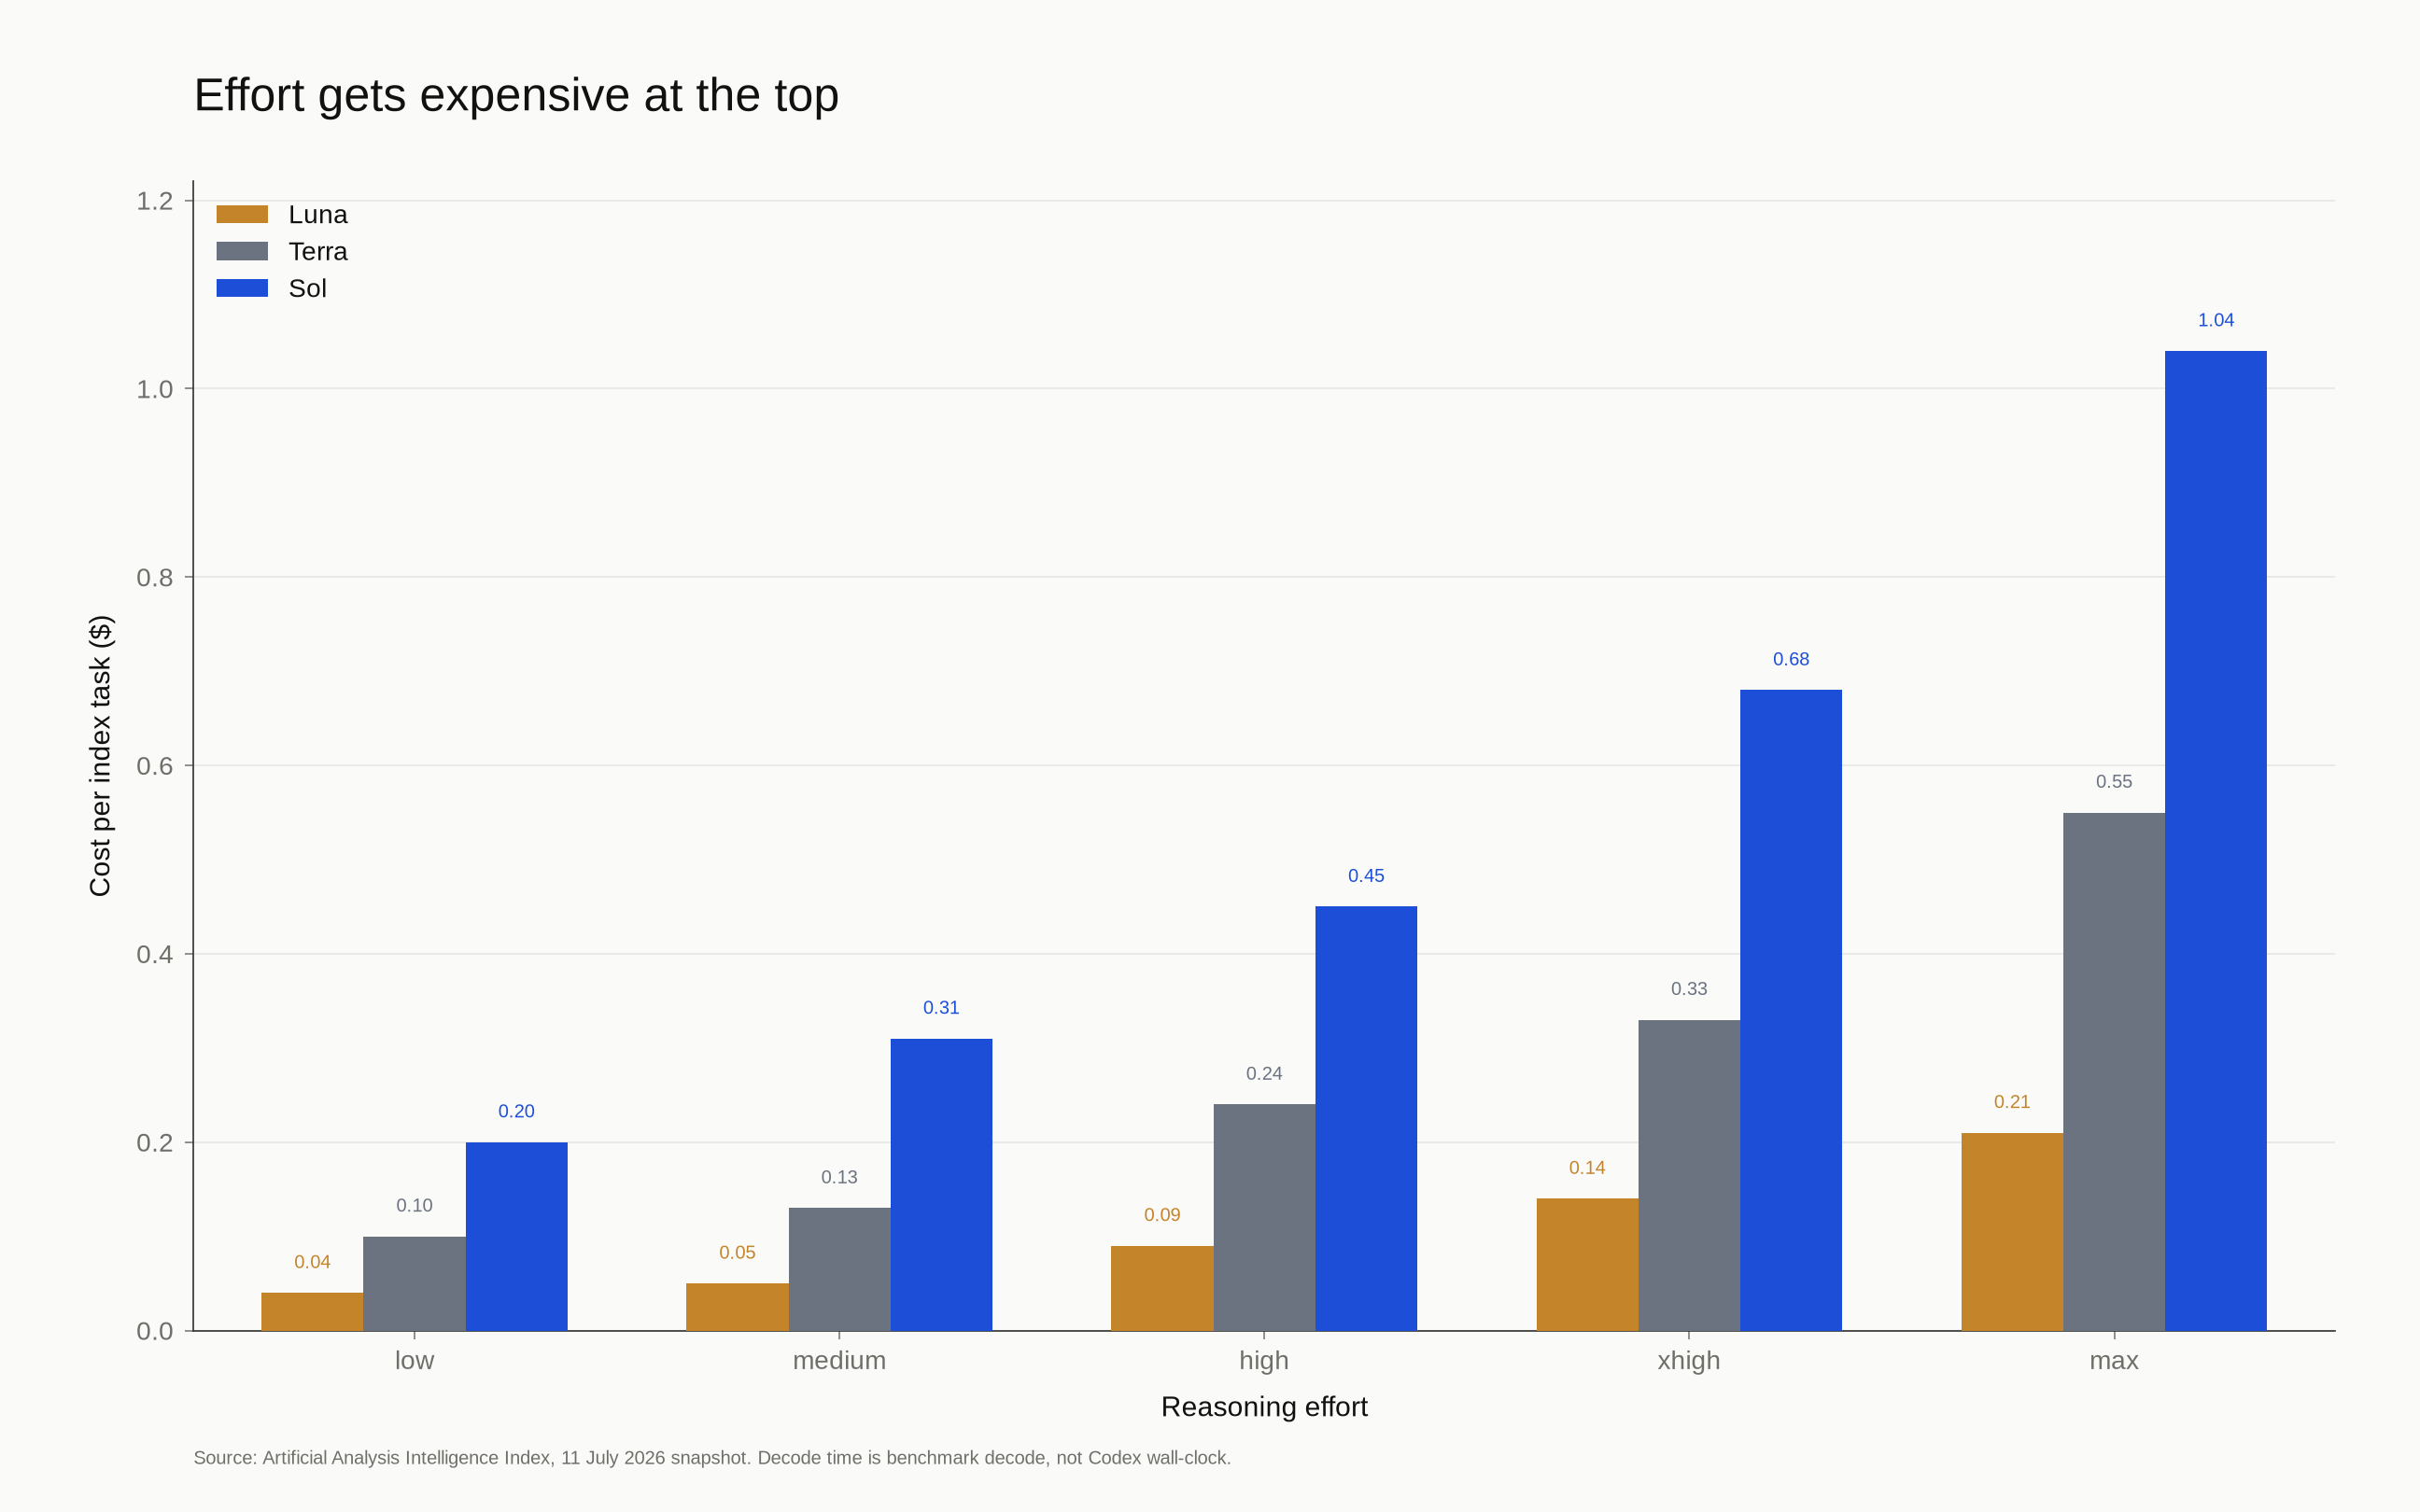
On that board, Sol low was already close to Luna max. Sol xhigh to Sol max almost doubled the task cost for one point.
Fast mode
Fast mode is up to 2.5× Standard speed for Sol, at 2× the token price. Intelligence does not change. Short-context Sol Fast is $8 / $40 per million.
I use it when I am blocked. I do not use it to make an overnight job feel premium. Measure it in the editor. The blog multiplier is not a local SLA.
Waiting is the bill
A minute of my time at £150/hour is £2.50. The token line is usually smaller.
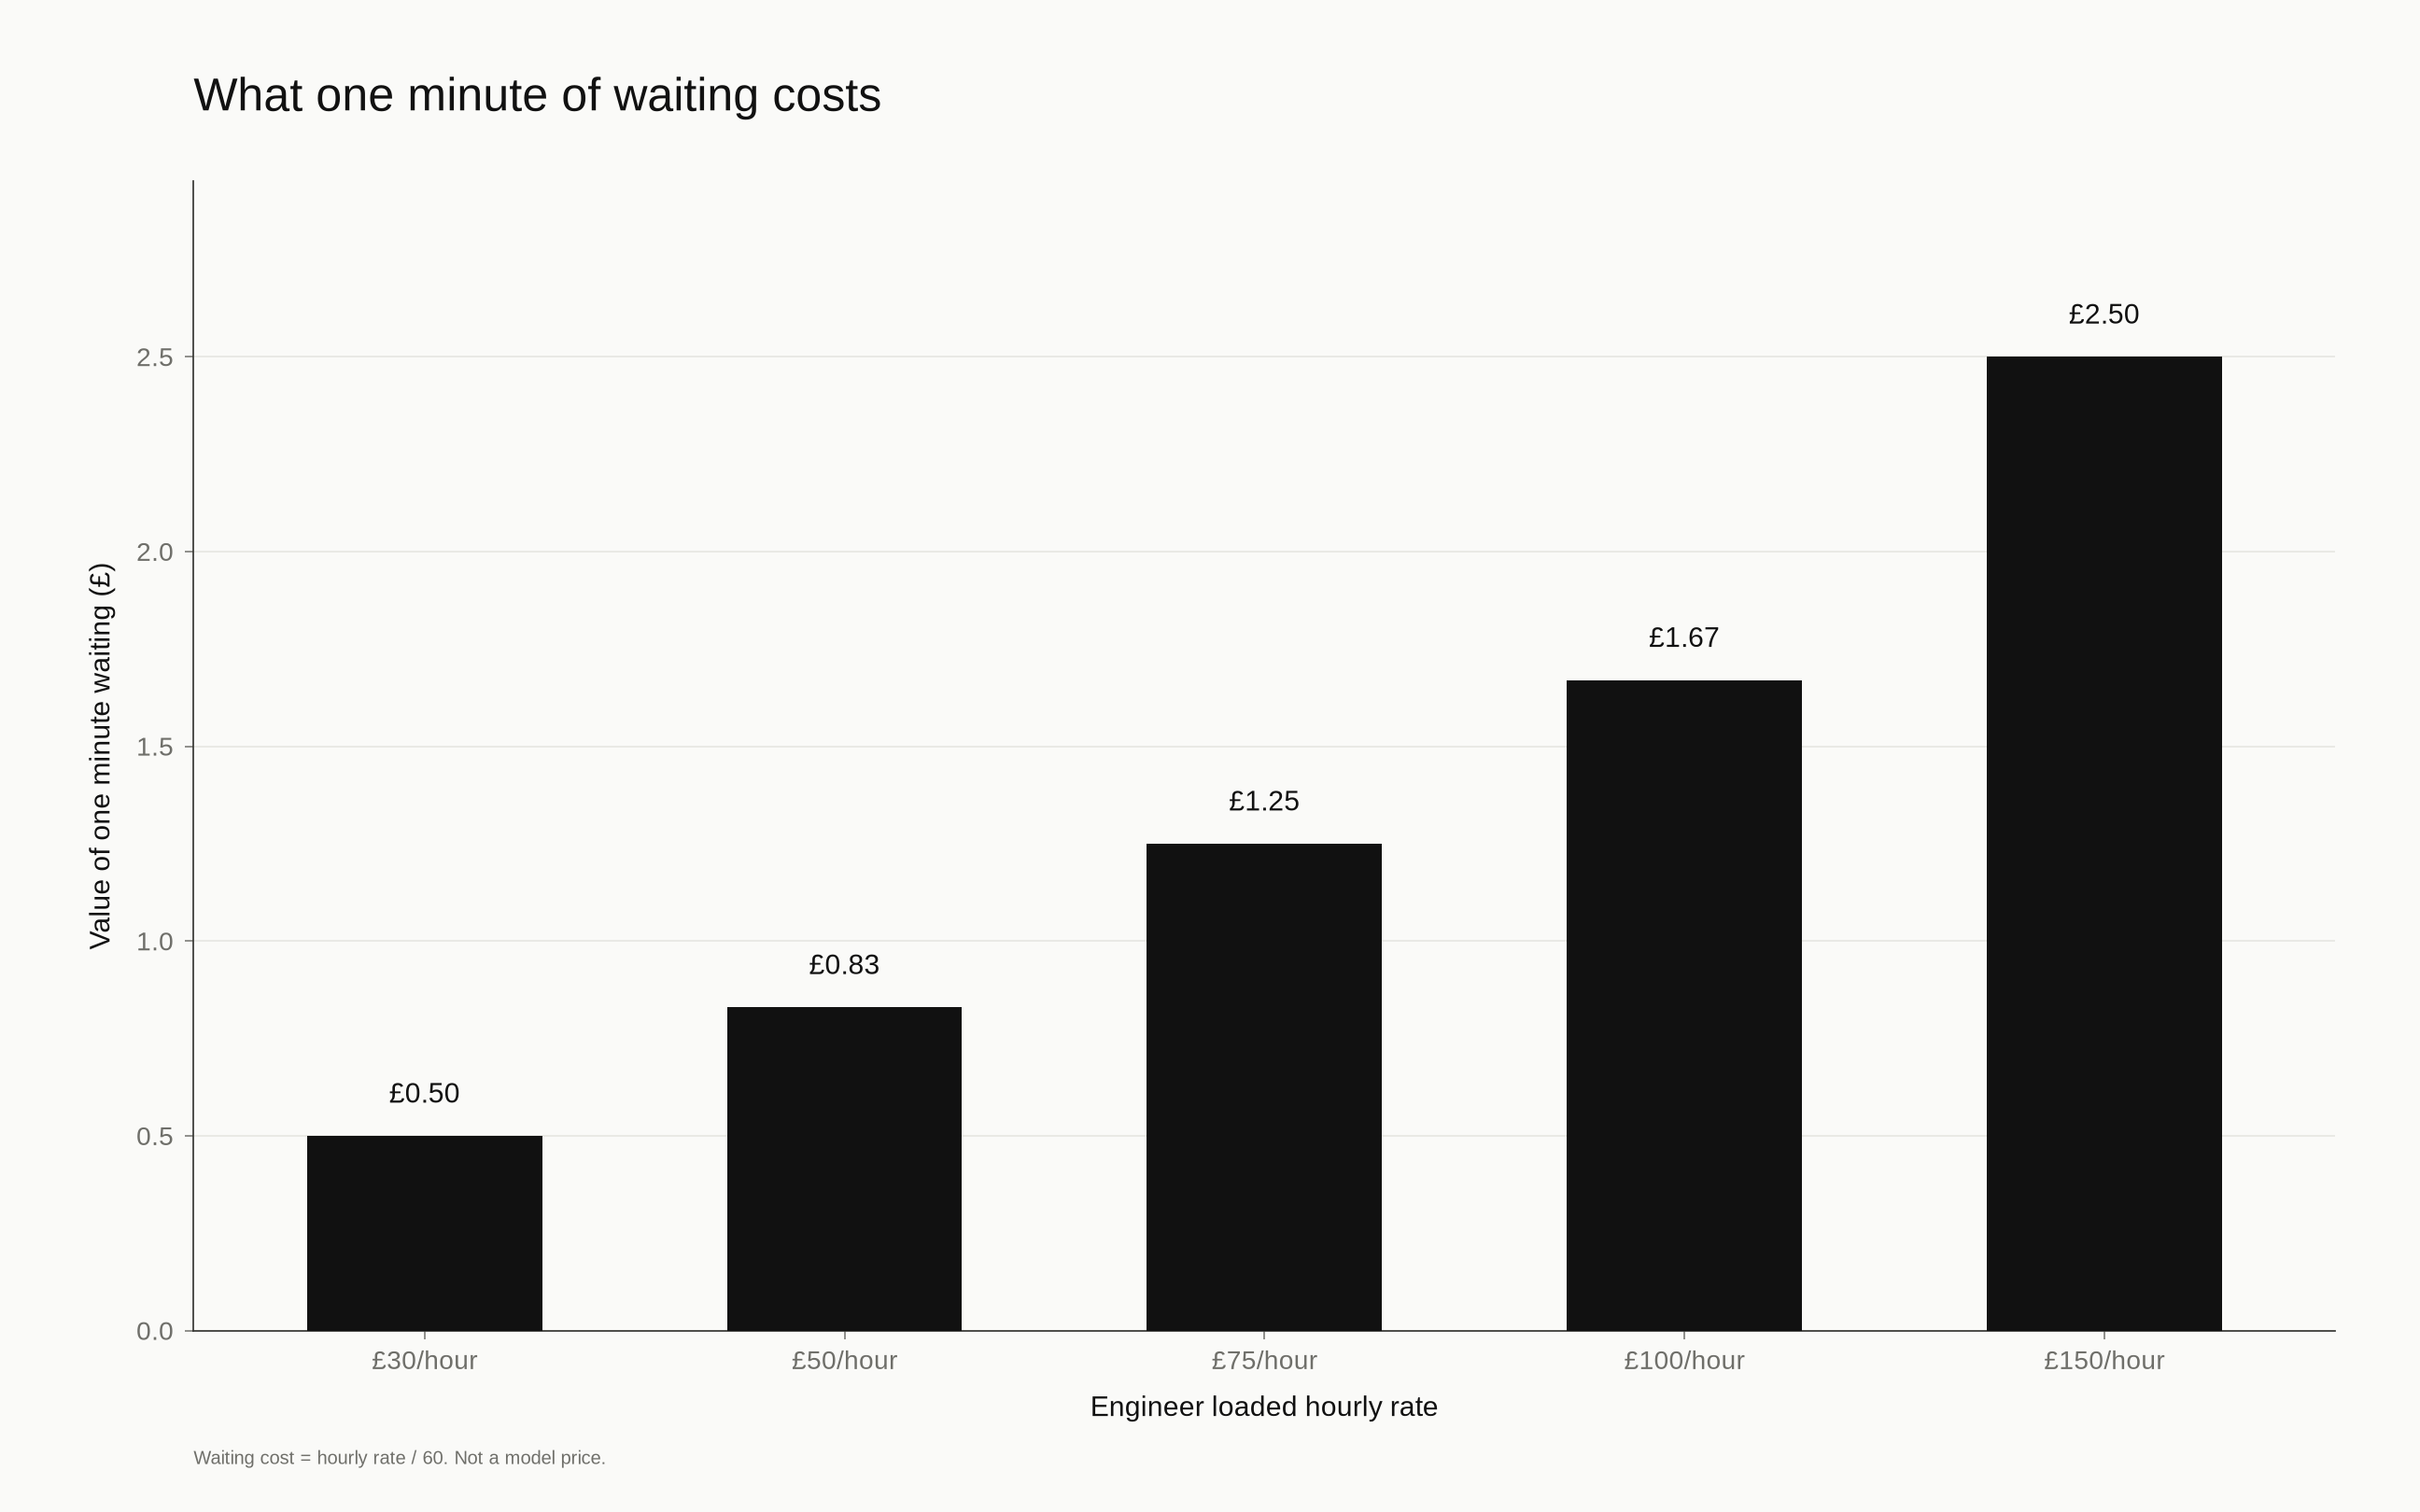
If I am sitting there, Sol Fast can be rational. If I am not, I buy the cheapest setting that still lands the change.
Sol decides. Luna types.
I use Sol for the spec, the review and the cut that is expensive to unwind. I use Luna to write the code, fill the tests and apply the plan.
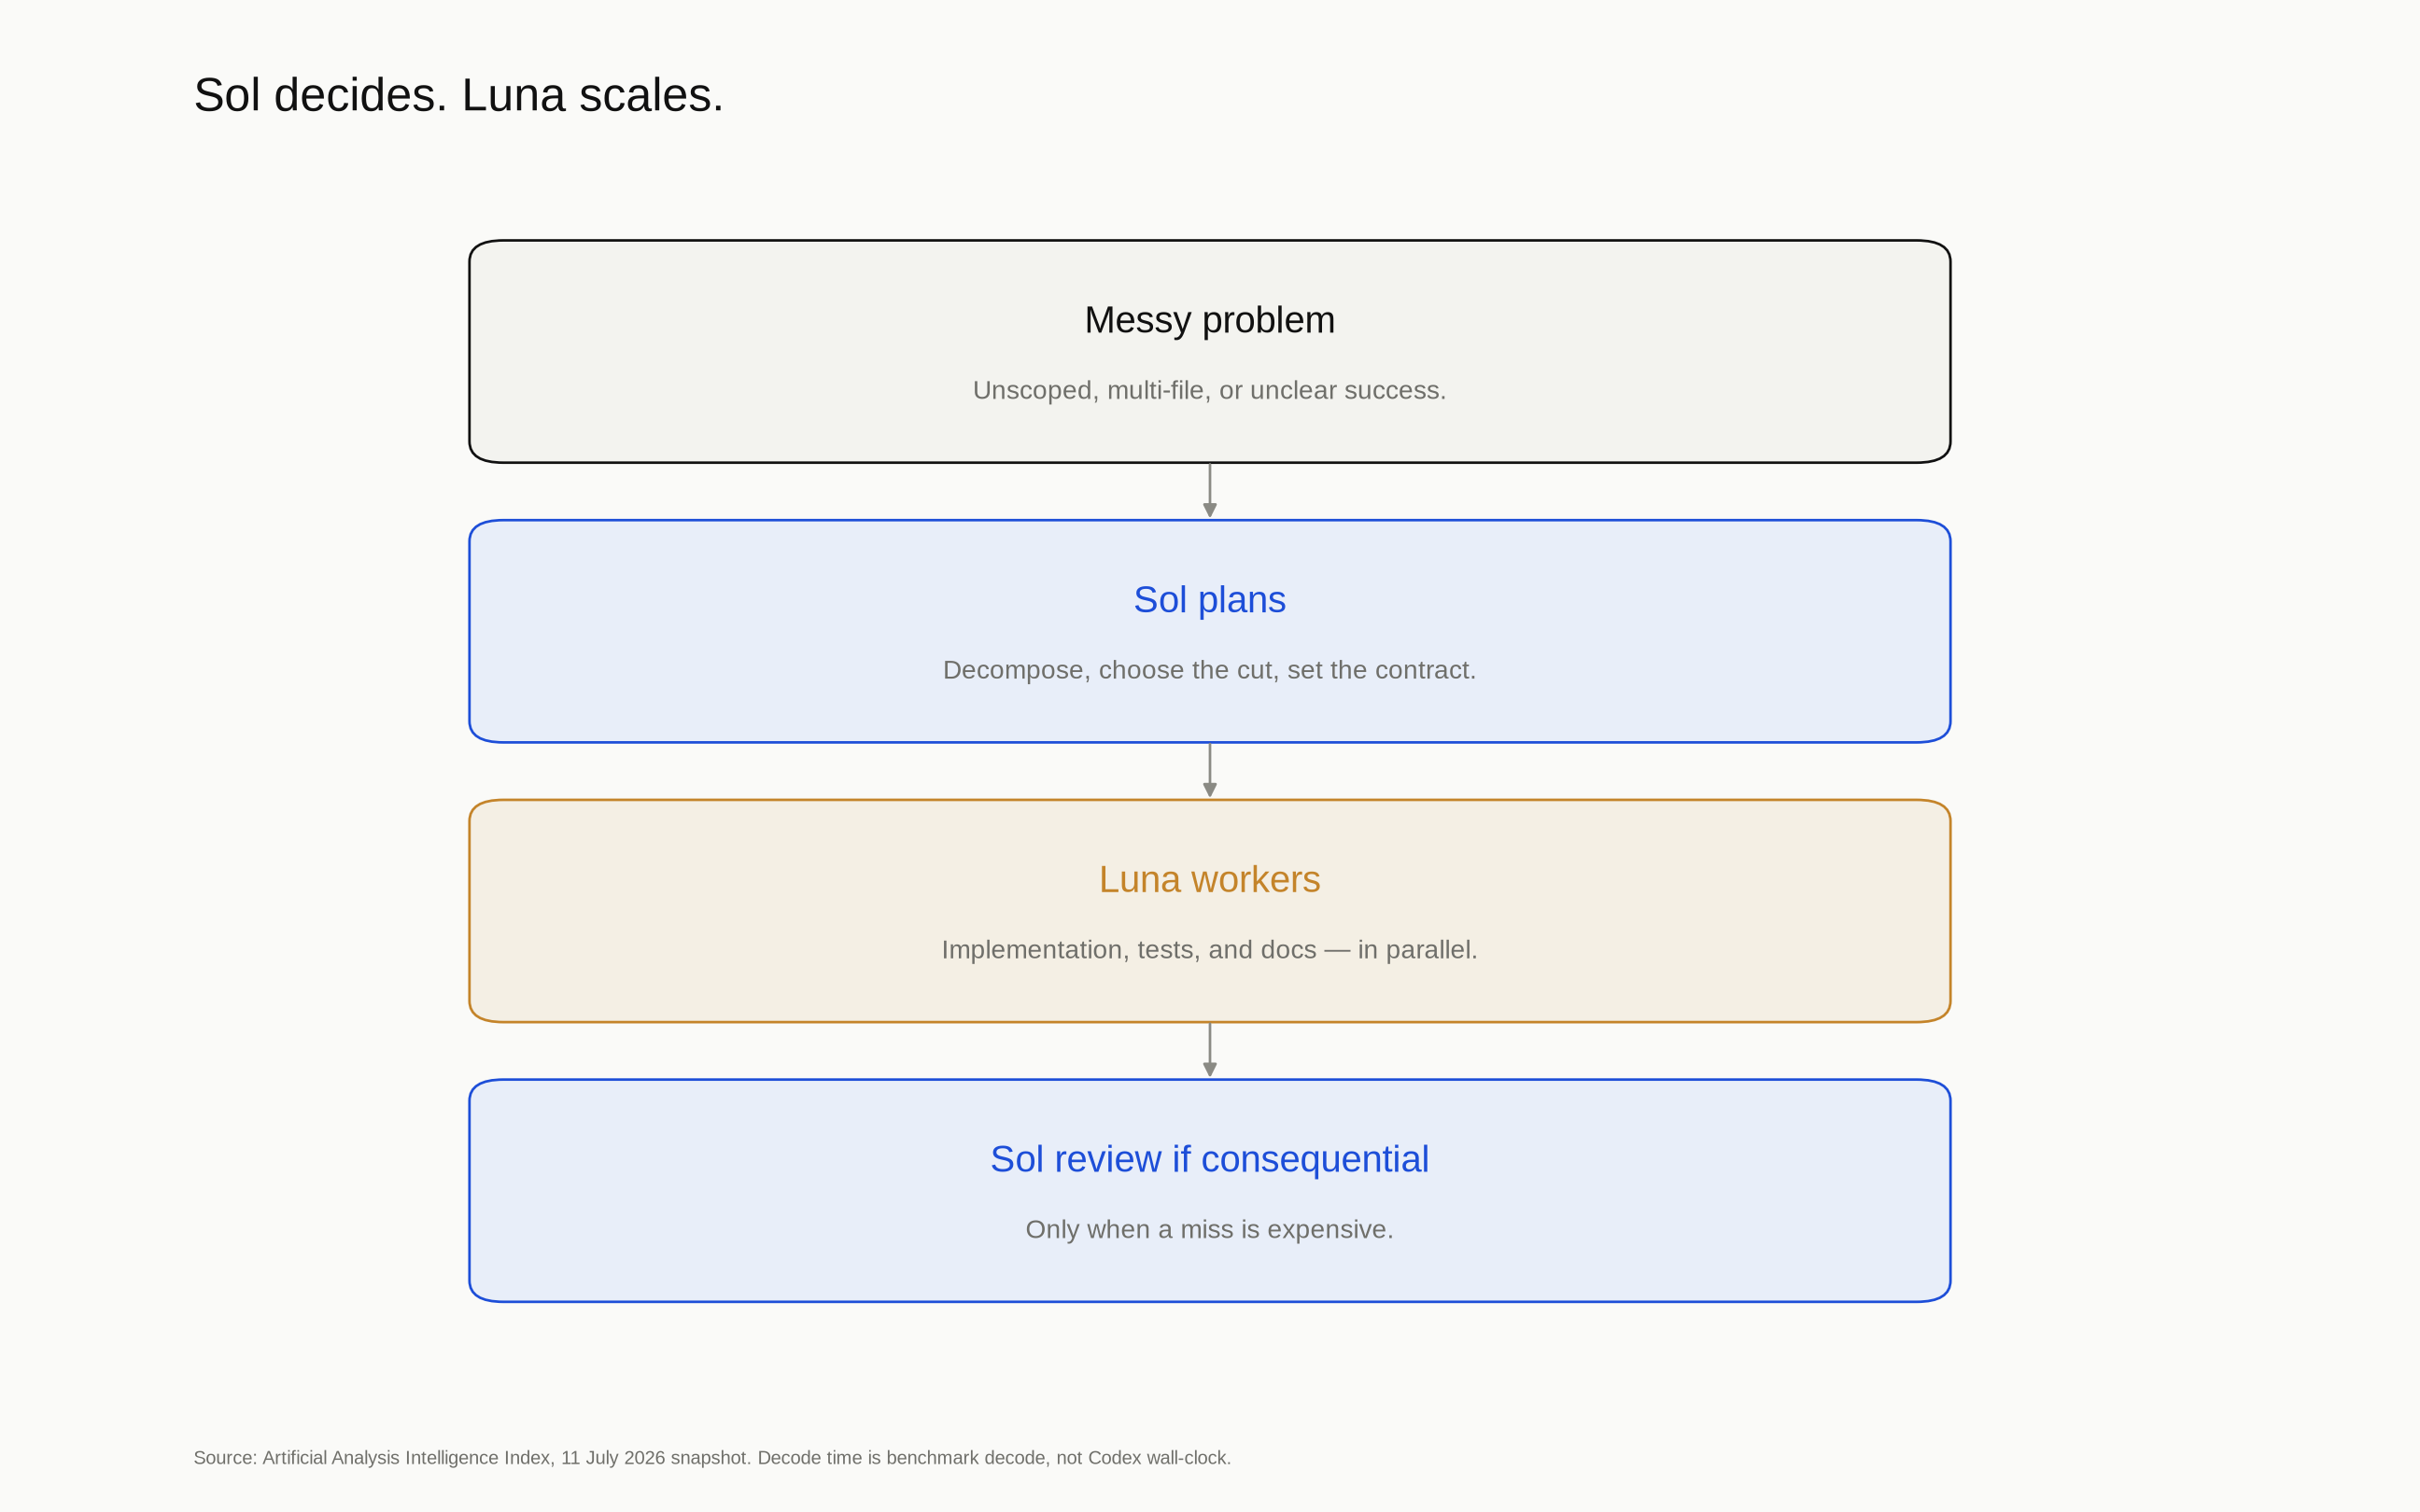
Most edits stay on Luna medium. Architecture, quiet bugs and migrations go to Sol. Fast only while I am blocked. Max is an exception I can explain.
Uncertainty and consequence
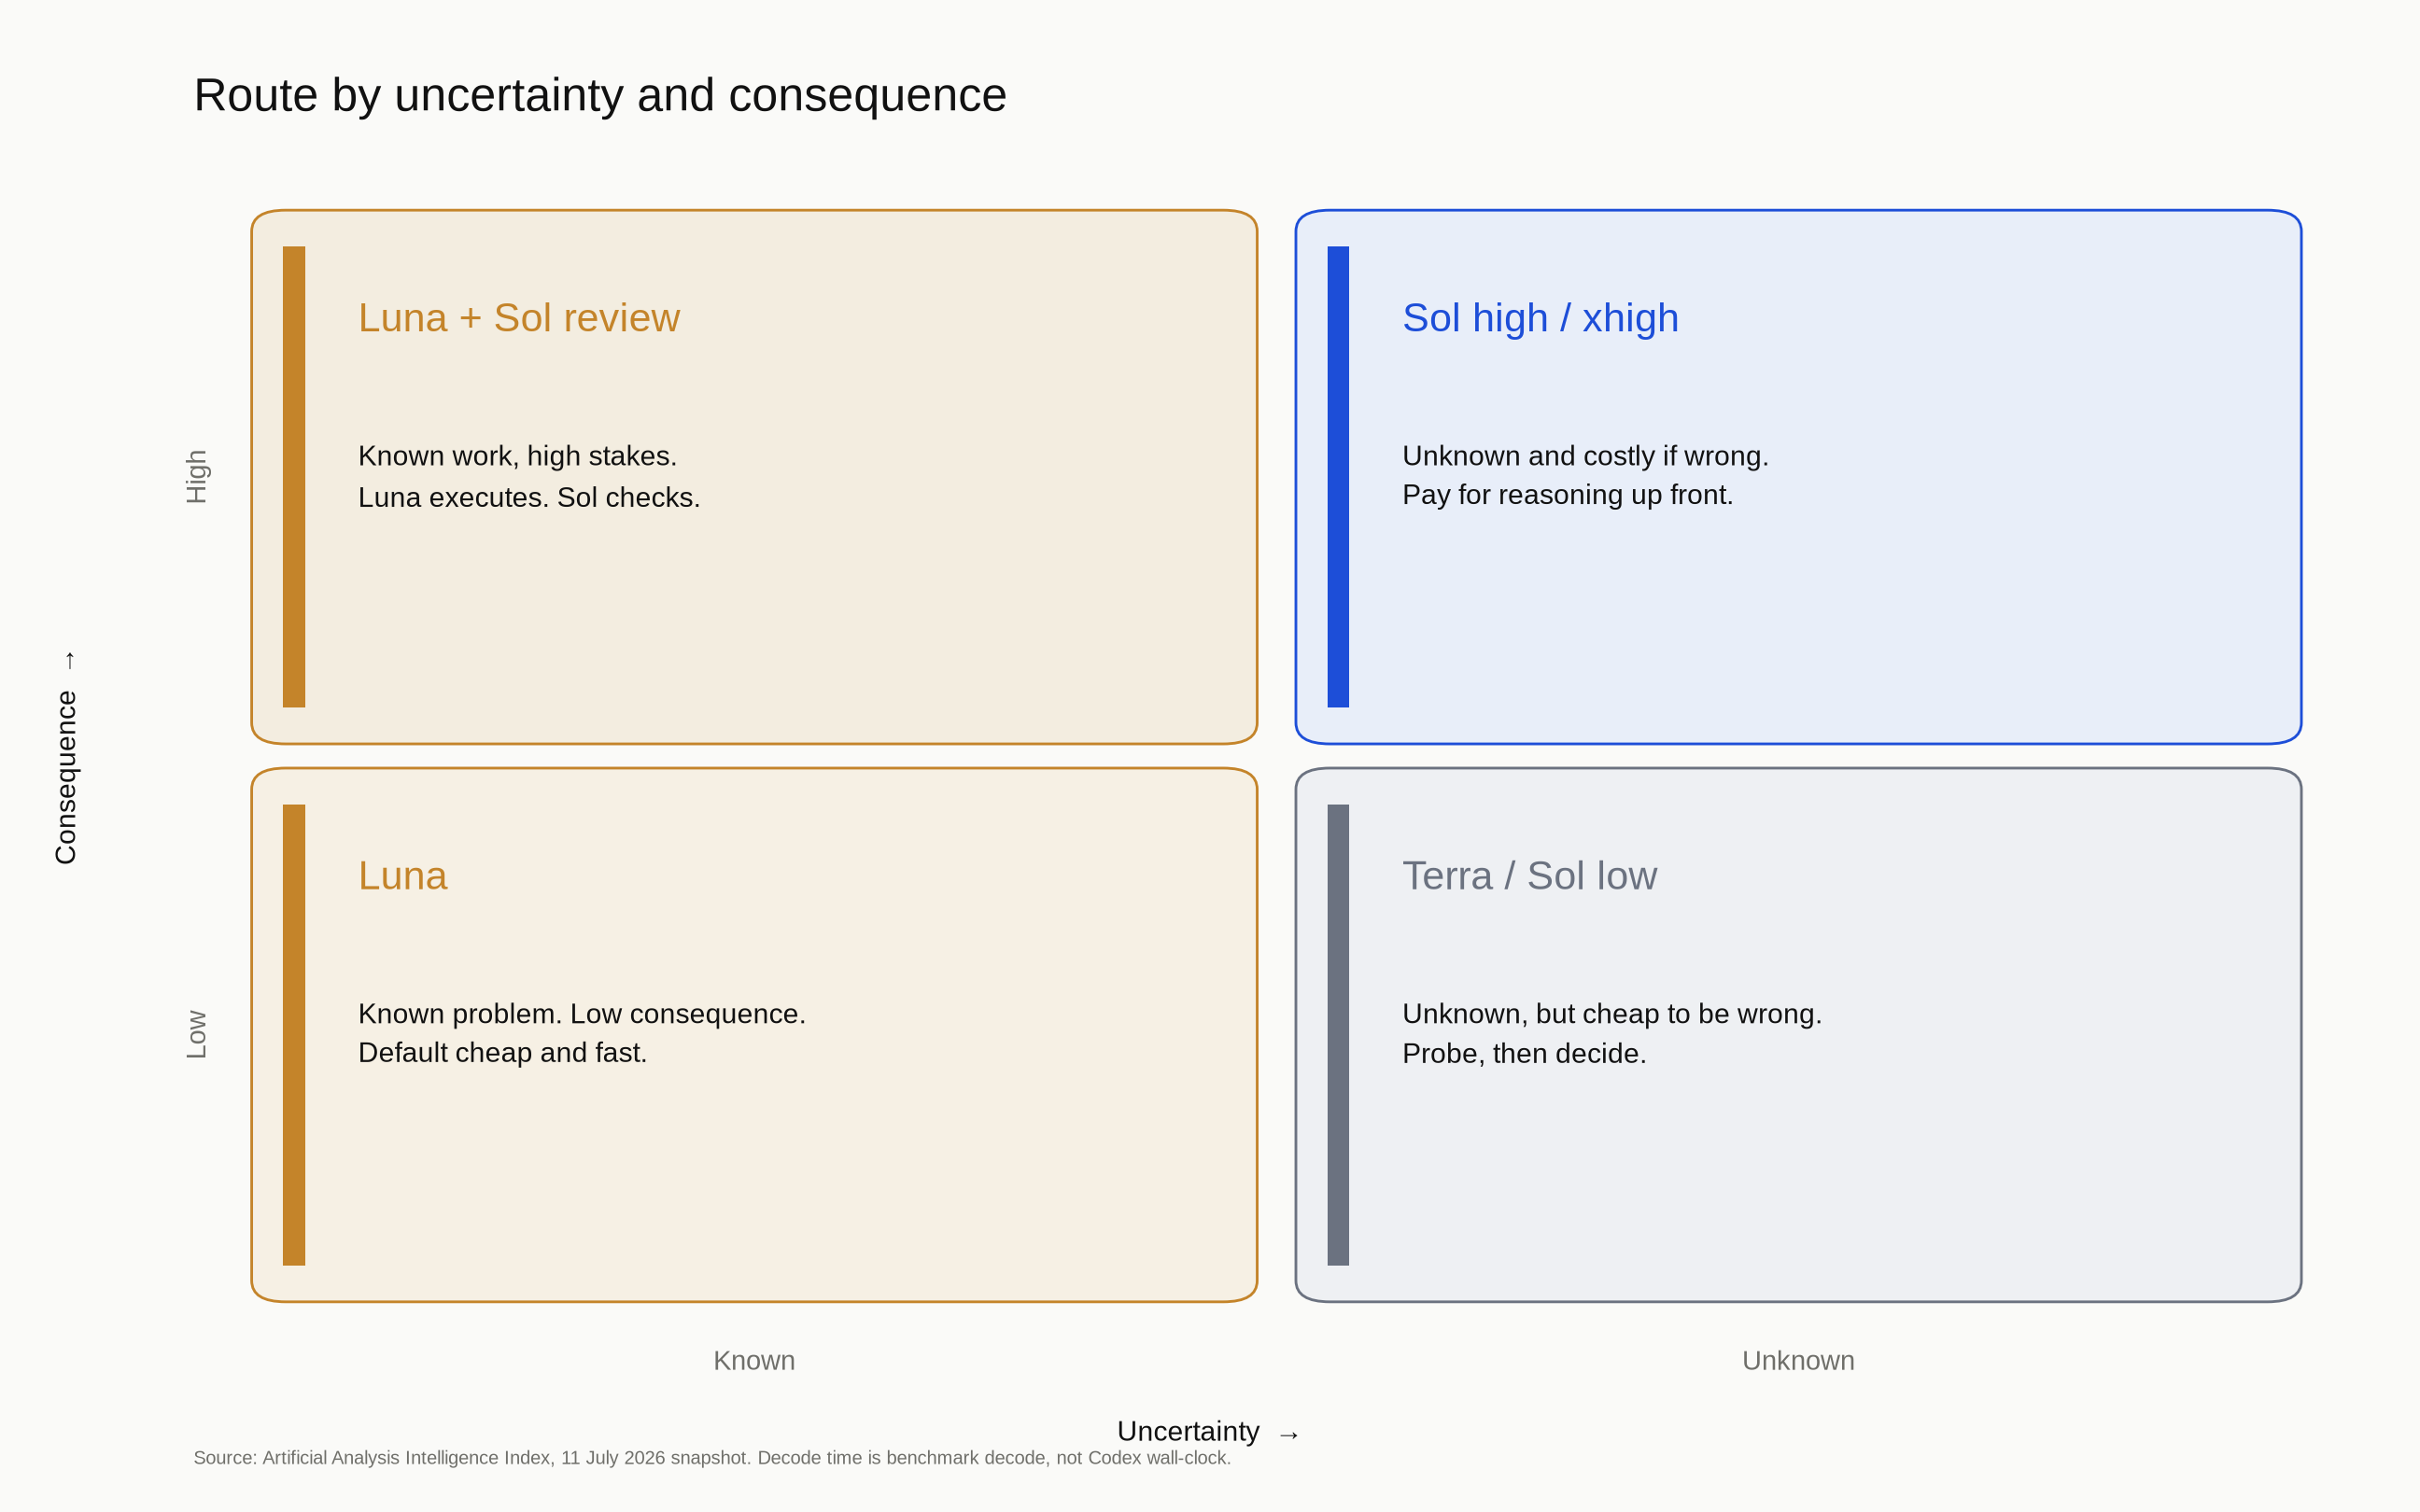
Known and cheap to miss: Luna.
Known and expensive to miss: Luna does the work. Sol checks. The test suite still has to pass.
Unknown and cheap to miss: Terra or Sol low. I throw the branch away if it is ugly.
Unknown and expensive to miss: Sol high or xhigh on the plan. Luna on the typing. I review as if Luna will miss something.
Always Sol max is a refusal to decide. Banning Sol to save money is how you buy a silent bug.
The prices are from 28 August 2026. The charts are the 11 July Artificial Analysis snapshot. If those numbers move, the question does not. What am I short of?